Skip to content · ⁨ข้ามไปยังเนื้อหา⁩

Sampling Distributions · ⁨การแจกแจงจากการสุ่มตัวอย่าง⁩

AP Statistics · Topic 5 · ⁨หัวข้อ 5⁩

Video lesson for this topic · ⁨บทเรียนวิดีโอสำหรับหัวข้อนี้⁩ Open the video page · ⁨เปิดหน้าวิดีโอ⁩
7:32

การแจกแจงจากการสุ่มตัวอย่าง

นักเรียนสองพันคนเรียนอยู่ที่โรงเรียนแห่งหนึ่ง และมีบางคนขี่จักรยานมาเรียน เราต้องการทราบสัดส่วนของผู้ที่ขี่จักรยาน ไม่มีใครสามารถสอบถามนักเรียนทั้งหมดสองพันคนได้ จึงเลือกสุ่มถามนักเรียนจำนวนหนึ่งร้อยคน…

English narration · English + 中文 subtitles burned in · ⁨การบรรยายภาษาอังกฤษ · คำบรรยายภาษาอังกฤษ + 中文 ลอยตัวบนภาพ⁩

5.1

Why Two Samples Never Match: Sampling Variability · ⁨ทำไมตัวอย่างสองชุดจึงไม่เคยเหมือนกัน: ความแปรปรวนจากการสุ่ม⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (VAR-1): Given that variation may be random or not, conclusions are uncertain.

Learning Objective VAR-1.G: Identify questions suggested by variation in statistics for samples collected from the same population. [Skill 1.A]

  • VAR-1.G.1 Variation in statistics for samples taken from the same population may be random or not.
ไทย

ความเข้าใจที่ยั่งยืน (VAR-1): เนื่องจากความแปรปรวนอาจเป็นแบบสุ่มหรือไม่ ดังนั้นข้อสรุปจึงมีความไม่แน่นอน

วัตถุประสงค์การเรียนรู้ VAR-1.G: ระบุคำถามที่เสนอจากการแปรปรวนของสถิติสำหรับตัวอย่างที่เก็บจากประชากรเดียวกัน [ทักษะ 1.A]

  • VAR-1.G.1 ความแปรปรวนของสถิติสำหรับตัวอย่างที่ Taken จากประชากรเดียวกันอาจเป็นแบบสุ่มหรือไม่ก็ได้อีกด้วย
Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

A statistic 统计量 (like a sample mean $\bar{x}$ or sample proportion $\hat{p}$) is computed from a sample and varies from sample to sample – this is sampling variability 抽样变异. A parameter 参数 ($\mu$ or $p$) is the fixed truth about the population. The sampling distribution 抽样分布 is the distribution of a statistic over all possible samples of a given size – it is the bridge from one sample to inference.

ไทย

สถิติ (เช่น ค่าเฉลี่ยตัวอย่าง $\bar{x}$ หรืออัตราส่วนตัวอย่าง $\hat{p}$) คำนวณจากตัวอย่างและ เปลี่ยนแปลง จากตัวอย่างไปยังตัวอย่าง – นี่คือ ความแปรปรวนจากการสุ่ม พารามิเตอร์ ($\mu$ หรือ $p$) เป็นความจริงที่แน่นอนเกี่ยวกับประชากร การแจกแจงจากการสุ่ม คือการแจกแจงของสถิติเหนือตัวอย่างที่เป็นไปได้ทั้งหมดที่มีขนาดที่กำหนด – มันเป็นสะพานเชื่อมจากตัวอย่างหนึ่งไปสู่การอนุมาน

5.2

The Normal Curve as a Model for a Statistic · ⁨เส้นโค้งปกติในฐานะโมเดลสำหรับสถิติ⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (VAR-6): The normal distribution may be used to model variation.

Learning Objective VAR-6.A: Calculate the probability that a particular value lies in a given interval of a normal distribution. [Skill 3.A]

  • VAR-6.A.1 A continuous random variable is a variable that can take on any value within a specified domain. Every interval within the domain has a probability associated with it.
  • VAR-6.A.2 A continuous random variable with a normal distribution is commonly used to describe populations. The distribution of a normal random variable can be described by a normal, or "bell-shaped," curve.
  • VAR-6.A.3 The area under a normal curve over a given interval represents the probability that a particular value lies in that interval.
    • Illustrative examples for VAR-6.A: Continuous random variable: If one looks at a clock at a random time, the probability that the minute hand is between the 3 and the 6 is one fourth.

Learning Objective VAR-6.B: Determine the interval associated with a given area in a normal distribution. [Skill 3.A]

  • VAR-6.B.1 The boundaries of an interval associated with a given area in a normal distribution can be determined using $z$-scores or technology, such as a calculator, a standard normal table, or computer-generated output.
  • VAR-6.B.2 Intervals associated with a given area in a normal distribution can be determined by assigning appropriate inequalities to the boundaries of the intervals:
    • a. $P(X < x_a) = \dfrac{p}{100}$ means that the lowest $p\%$ of values lie to the left of $x_a$.
    • b. $P(x_a < X < x_b) = \dfrac{p}{100}$ means that $p\%$ of values lie between $x_a$ and $x_b$.
    • c. $P(X > x_b) = \dfrac{p}{100}$ means that the highest $p\%$ of values lie to the right of $x_b$.
    • d. To determine the most extreme $p\%$ of values requires dividing the area associated with $p\%$ into two equal areas on either extreme of the distribution: $P(X < x_a) = \dfrac{1}{2}\dfrac{p}{100}$ and $P(X > x_b) = \dfrac{1}{2}\dfrac{p}{100}$ means that half of the $p\%$ most extreme values lie to the left of $x_a$ and half of the $p\%$ most extreme values lie to the right of $x_b$.

Learning Objective VAR-6.C: Determine the appropriateness of using the normal distribution to approximate probabilities for unknown distributions. [Skill 3.C]

  • VAR-6.C.1 Normal distributions are symmetrical and "bell-shaped." As a result, normal distributions can be used to approximate distributions with similar characteristics.
ไทย

ความเข้าใจที่ยั่งยืน (VAR-6): การแจกแจงปกติสามารถใช้สร้างแบบจำลองความแปรปรวนได้

วัตถุประสงค์การเรียนรู้ VAR-6.A: คำนวณความน่าจะเป็นที่ค่าเฉพาะจะอยู่ในช่วงที่กำหนดของการแจกแจงปกติ [ทักษะ 3.A]

  • VAR-6.A.1 ตัวแปรสุ่มแบบต่อเนื่องคือตัวแปรที่สามารถรับค่าใดๆ Within一个指定域ได้ ทุกช่วงภายในโดเมนจะมีความน่าจะเป็นที่เกี่ยวข้องกับมัน
  • VAR-6.A.2 ตัวแปรสุ่มแบบต่อเนื่องที่มีการแจกแจงปกติมักใช้เพื่ออธิบายประชากร การแจกแจงของตัวแปรสุ่มแบบปกติสามารถอธิบายได้ด้วยcurve แบบปกติ หรือ "รูปทรงกระดิ่ง"
  • VAR-6.A.3 พื้นที่ใต้ curve ปกติเหนือช่วงที่กำหนดแสดงถึงความน่าจะเป็นที่ค่าเฉพาะจะอยู่ในช่วงนั้น
    • ตัวอย่างประกอบสำหรับ VAR-6.A: ตัวแปรสุ่มแบบต่อเนื่อง: หากมองนาฬิกาในช่วงเวลาสุ่ม, ความน่าจะเป็นที่เข็มนาทีจะอยู่ระหว่างเลข 3 และ 6 คือหนึ่งในสี่

วัตถุประสงค์การเรียนรู้ VAR-6.B: กำหนดช่วงที่สัมพันธ์กับพื้นที่ที่กำหนดในการแจกแจงปกติ [ทักษะ 3.A]

  • VAR-6.B.1 ขอบเขตของช่วง associated กับพื้นที่ที่กำหนดใน distribution ปกติสามารถหาได้โดยใช้ $z$-scores หรือเทคโนโลยี เช่น เครื่องคิดเลข, ตาราง normal standard, หรือ output ที่สร้างโดยคอมพิวเตอร์
  • VAR-6.B.2 ช่วงที่สัมพันธ์กับพื้นที่ที่กำหนดในการแจกแจงปกติสามารถกำหนดได้โดยการกำหนดอสมการที่เหมาะสมให้กับขอบเขตของช่วง:
    • a. $P(X < x_a) = \dfrac{p}{100}$ หมายความว่า $p\%$ ของค่าต่ำสุดอยู่ทางซ้ายของ $x_a$
    • b. $P(x_a < X < x_b) = \dfrac{p}{100}$ หมายความว่า $p\%$ ของค่าอยู่ระหว่าง $x_a$ และ $x_b$
    • c. $P(X > x_b) = \dfrac{p}{100}$ หมายความว่า $p\%$ ของค่าสูงสุดอยู่ทางขวาของ $x_b$
    • d. เพื่อหาค่าที่ extreme ที่สุด $p\%$ ของค่า Requiresการแบ่งพื้นที่ที่เกี่ยวข้องกับ $p\%$ เป็นสองส่วนเท่ากันที่ extreme ของทั้งสองข้างของการแจกแจง: $P(X < x_a) = \dfrac{1}{2}\dfrac{p}{100}$ และ $P(X > x_b) = \dfrac{1}{2}\dfrac{p}{100}$ หมายความว่าครึ่งหนึ่งของ $p\%$ ค่าที่ extreme ที่สุดอยู่ทางซ้ายของ $x_a$ และครึ่งหนึ่งของ $p\%$ ค่าที่ extreme ที่สุดอยู่ทางขวาของ $x_b$

วัตถุประสงค์การเรียนรู้ VAR-6.C: determination ความเหมาะสมของการใช้การแจกแจงปกติเพื่อประมาณความน่าจะเป็นสำหรับการแจกแจงที่ไม่รู้จัก [ทักษะ 3.C]

  • VAR-6.C.1 การแจกแจงปกติมีความสมมาตรและเป็น "รูปทรงกระดิ่ง" ดังนั้น การแจกแจงปกติจึงสามารถใช้ประมาณการแจกแจงที่มีลักษณะคล้ายคลึงกันได้

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English
The normal distribution

For large enough samples, many sampling distributions are approximately normal. That lets us describe a statistic by a center (its mean), a spread (its standard error 标准误), and a normal shape – and then compute how likely a given sample result is.

ไทย
การแจกแจงปกติ

สำหรับตัวอย่างที่มีขนาดใหญ่พอ การแจกแจงจากการสุ่มหลายชนิดเป็นแบบ ปกติ อย่างประมาณการ สิ่งนี้ช่วยให้เราสามารถอธิบายสถิติด้วย จุดศูนย์กลาง (ค่าเฉลี่ย), การกระจายตัว (ส่วนเบี่ยงเบนมาตรฐาน), และรูปร่างแบบปกติ – และจากนั้นคำนวณว่าผลลัพธ์จากตัวอย่างที่กำหนดมีความน่าจะเป็นเท่าไร

Explore · ⁨สำรวจ⁩

Use the normal curve to find a proportion · ⁨ใช้เส้นโค้งปกติเพื่อหาสัดส่วน⁩

A normal model turns a range of values into an area = a proportion. Shade a band to read off the fraction of samples falling within it (the 68-95-99.7 rule). · ⁨โมเดล ปกติ (normal) เปลี่ยนช่วงของค่าให้เป็น พื้นที่ = สัดส่วน การทาสีแถบเพื่ออ่านเศษส่วนของตัวอย่างที่ตกอยู่ในช่วงนั้น (กฎ 68-95-99.7)⁩

5.3

The Central Limit Theorem · ⁨theorem ขอบเขตกลาง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.H: Estimate sampling distributions using simulation. [Skill 3.C]

  • UNC-3.H.1 A sampling distribution of a statistic is the distribution of values for the statistic for all possible samples of a given size from a given population.
  • UNC-3.H.2 The central limit theorem (CLT) states that when the sample size is sufficiently large, a sampling distribution of the mean of a random variable will be approximately normally distributed.
  • UNC-3.H.3 The central limit theorem requires that the sample values are independent of each other and that $n$ is sufficiently large.
  • UNC-3.H.4 A randomization distribution is a collection of statistics generated by simulation assuming known values for the parameters. For a randomized experiment, this means repeatedly randomly reallocating/reassigning the response values to treatment groups.
  • UNC-3.H.5 The sampling distribution of a statistic can be simulated by generating repeated random samples from a population.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.H: ประมาณการแจกแจงตัวอย่างโดยใช้การจำลอง [ทักษะ 3.C]

  • UNC-3.H.1 การแจกแจงตัวอย่างของสถิติคือการแจกแจงของค่าสำหรับสถิติสำหรับทุกตัวอย่างที่เป็นไปได้ที่มีขนาด给定จากประชากร给定
  • UNC-3.H.2 ทฤษฎีบทขีดจำกัดกลาง (CLT) ระบุว่าเมื่อขนาดตัวอย่างมีขนาดใหญ่พอ, การแจกแจงตัวอย่างของค่าเฉลี่ยของตัวแปรสุ่มจะประมาณเป็นการแจกแจงปกติ
  • UNC-3.H.3 ทฤษฎีบทขีดจำกัดกลางต้องการให้ค่าตัวอย่างเป็นอิสระต่อกันและ $n$ มีขนาดใหญ่เพียงพอ
  • UNC-3.H.4 การแจกแจงการสุ่มคือชุดของสถิติที่สร้าง由การจำลอง assuming known values for the parameters. สำหรับexperiment แบบสุ่ม, นี้หมายถึงการจัดสรร/จัดกลุ่มค่าการตอบสนองซ้ำๆ แบบสุ่มไปยังกลุ่มการรักษา
  • UNC-3.H.5 การแจกแจงตัวอย่างของสถิติสามารถจำลองได้โดยการสร้างตัวอย่างสุ่มซ้ำๆ จากประชากร

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English
The Central Limit Theorem

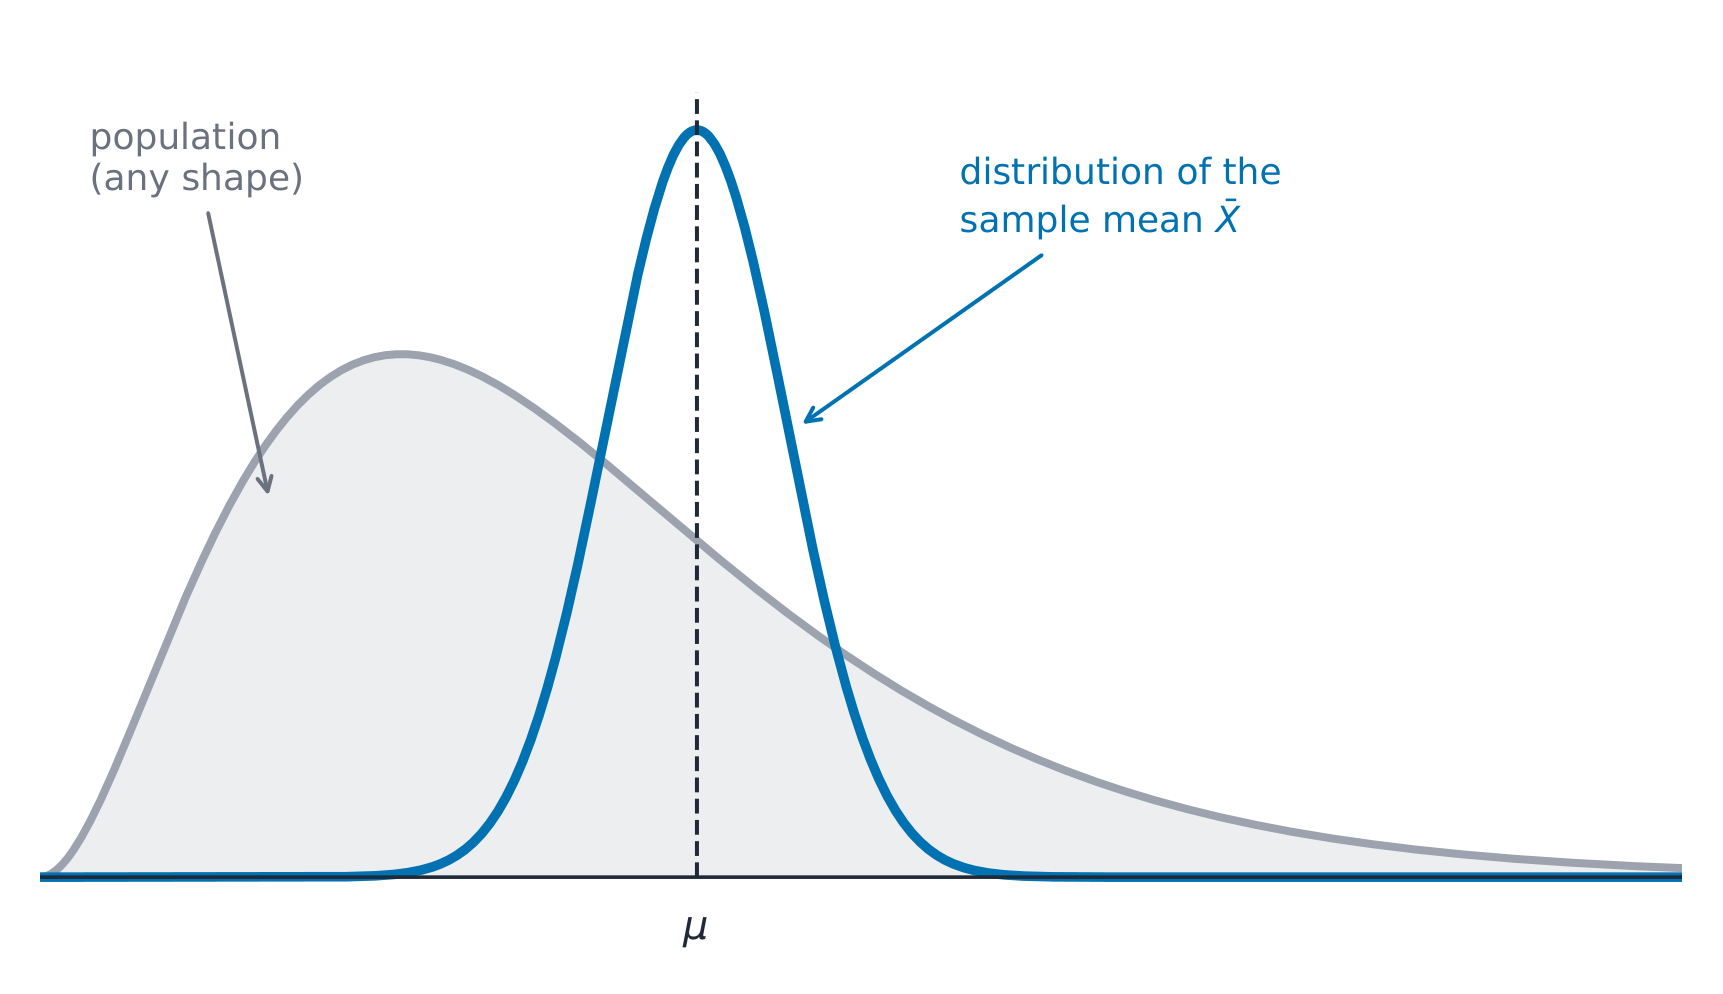
The Central Limit Theorem 中心极限定理 (CLT): for a sample mean, if the sample size $n$ is large enough (a common rule is $n\ge 30$), the sampling distribution of $\bar{x}$ is approximately normal, regardless of the population's shape. The larger $n$, the more normal and the tighter the distribution.

ไทย
ทฤษฎีบทขีดจำกัดกลาง

ทฤษฎีบท-limit-กลาง (Central Limit Theorem - CLT): สำหรับ sample mean, หากขนาดตัวอย่าง $n$ เพียงพอ (common rule is $n\ge 30$), sampling distribution of $\bar{x}$ จะ approximately normal, ไม่ขึ้นกับรูปร่างของ population. ยิ่ง $n$越大,越 normal และ越 tight the distribution becomes.

sample mean will be nearly normal regardless of population shape
ค่าเฉลี่ยตัวอย่างเป็นแบบปกติเกือบเสมอไม่ว่ารูปร่างของประชากรจะเป็นอย่างไร
Explore · ⁨สำรวจ⁩

Watch a sampling distribution turn normal · ⁨ดูการกระจายตัวอย่างกลายเป็นปกติ⁩

The Central Limit Theorem: for a large enough sample, the distribution of the sample mean is approximately normal — whatever the shape of the population. · ⁨ทฤษฎีบทحدกึ่งกลาง: สำหรับตัวอย่างที่ใหญ่พอ การกระจายของ ค่าเฉลี่ย ตัวอย่างจะเป็น ปกติ โดยประมาณ — ไม่ว่ารูปทรงของประชากรจะเป็นอย่างไร⁩

Vocabulary · ⁨คำศัพท์⁩ Train · ⁨ฝึกฝน⁩
English ไทย
statistic/stəˈtɪstɪk/ ค่าสถิติ
sampling variability/ˈsæmplɪŋ ˌveərɪəˈbɪlɪti/ ความแปรปรวนจากการสุ่ม (sampling variability)
sampling distribution/ˈsæmplɪŋ ˌdɪstrɪˈbjuːʃn/ การแจกแจงตัวอย่าง
Central Limit Theorem/ˈsentrəl ˈlɪmɪt ˈθɪərəm/ ทฤษฎีบทحدกลาง
unbiased/ʌnˈbaɪəst/ ไม่มีอคติ (unbiased)
5.4

Good Guesses and Bad Guesses: Bias · ⁨การคาดเดาที่ดีและไม่ดี: ความเอนเอียง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.I: Explain why an estimator is or is not unbiased. [Skill 4.B]

  • UNC-3.I.1 When estimating a population parameter, an estimator is unbiased if, on average, the value of the estimator is equal to the population parameter.

Learning Objective UNC-3.J: Calculate estimates for a population parameter. [Skill 3.B]

  • UNC-3.J.1 When estimating a population parameter, an estimator exhibits variability that can be modeled using probability.
  • UNC-3.J.2 A sample statistic is a point estimator of the corresponding population parameter.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.I: อธิบายเหตุผลที่ตัวประมาณค่าเป็นหรือไม่เป็นความลำเอียง [ทักษะ 4.B]

  • UNC-3.I.1 ในการประมาณพารามิเตอร์ของประชากร, ตัวประมาณค่าจะมีความลำเอียงหากโดยเฉลี่ยแล้ว, ค่าของตัวประมาณค่าเท่ากับพารามิเตอร์ของประชากร

วัตถุประสงค์การเรียนรู้ UNC-3.J: คำนวณค่าประมาณสำหรับพารามิเตอร์ของประชากร [ทักษะ 3.B]

  • UNC-3.J.1 เมื่อประมาณค่าพารามิเตอร์ของประชากร ตัวประมาณค่าจะมีความแปรปรวนซึ่งสามารถจำลองได้โดยใช้ความน่าจะเป็น
  • UNC-3.J.2 สถิติจากตัวอย่างเป็นค่าประมาณจุดของพารามิเตอร์ประชากรที่เกี่ยวข้อง

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

A statistic is unbiased 无偏 if the mean of its sampling distribution equals the parameter – it is correct on average. Bias is about the center being off; variability is about the spread. A good estimator is both unbiased (centered right) and low-variability (precise); larger samples reduce variability but do not fix bias from bad sampling.

ไทย

สถิติเป็น ไม่มีความเอนเอียง หากค่าเฉลี่ยของการแจกแจงจากการสุ่มของมันเท่ากับพารามิเตอร์ – มันถูกต้อง โดยเฉลี่ย ความเอนเอียงเกี่ยวข้องกับจุดศูนย์กลางที่คลาดเคลื่อน; ความแปรปรวน เกี่ยวข้องกับการกระจายตัว ตัวประมาณการที่ดีควรเป็นทั้งไม่มีความเอนเอียง (จุดศูนย์กลางถูก) และความแปรปรวนต่ำ (แม่นยำ); ตัวอย่างที่ใหญ่ขึ้นจะลดความแปรปรวนแต่ไม่แก้ไขความเอนเอียงจากการสุ่มที่ไม่ดี

Four sampling distributions crossing bias with variability, against the true parameter
ความเบี่ยงเบนและความแปรปรวนเป็นข้อผิดพลาดคนละประเภท ตัวประมาณค่าบนซ้ายเพียงตัวเดียวที่ BOTH อยู่ตรงกลาง $\theta$ และมีความหนาแน่น; ส่วนล่างซ้ายมีความแม่นยำแต่ ผิดมาโดยตลอด ซึ่งไม่มีข้อมูลเพิ่มใดจะแก้ไขได้
Vocabulary · ⁨คำศัพท์⁩ Train · ⁨ฝึกฝน⁩
English ไทย
parameter/pəˈræmɪtə/ พารามิเตอร์
5.5

The Sampling Distribution of a Sample Proportion · ⁨การแจกแจงของสัดส่วนตัวอย่าง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.K: Determine parameters of a sampling distribution for sample proportions. [Skill 3.B]

  • UNC-3.K.1 For independent samples (sampling with replacement) of a categorical variable from a population with population proportion, $p$, the sampling distribution of the sample proportion, $\hat{p}$, has a mean, $\mu_{\hat{p}} = p$ and a standard deviation, $\sigma_{\hat{p}} = \sqrt{\dfrac{p(1-p)}{n}}$.
  • UNC-3.K.2 If sampling without replacement, the standard deviation of the sample proportion is smaller than what is given by the formula above. If the sample size is less than 10% of the population size, the difference is negligible.

Learning Objective UNC-3.L: Determine whether a sampling distribution for a sample proportion can be described as approximately normal. [Skill 3.C]

  • UNC-3.L.1 For a categorical variable, the sampling distribution of the sample proportion, $\hat{p}$, will have an approximate normal distribution, provided the sample size is large enough: $np \geq 10$ and $n(1-p) \geq 10$

Learning Objective UNC-3.M: Interpret probabilities and parameters for a sampling distribution for a sample proportion. [Skill 4.B]

  • UNC-3.M.1 Probabilities and parameters for a sampling distribution for a sample proportion should be interpreted using appropriate units and within the context of a specific population.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.K: กำหนดพารามิเตอร์ของการแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่าง [ทักษะ 3.B]

  • UNC-3.K.1 สำหรับตัวอย่างที่เป็นอิสระ (การสุ่มตัวอย่างพร้อมการแทนที่) ของตัวแปรเชิงหมวดหมู่จากประชากรที่มีสัดส่วนประชากร $p$, การแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่าง, $\hat{p}$, จะมีค่าเฉลี่ย, $\mu_{\hat{p}} = p$ และส่วนเบี่ยงเบนมาตรฐาน, $\sigma_{\hat{p}} = \sqrt{\dfrac{p(1-p)}{n}}$
  • UNC-3.K.2 หากเป็นการสุ่มตัวอย่างโดยไม่มีการแทนที่ ส่วนเบี่ยงเบนมาตรฐานของสัดส่วนจากตัวอย่างจะมีค่าน้อยกว่าค่าที่ได้จากสูตรข้างต้น หากขนาดตัวอย่างมีค่าน้อยกว่า 10% ของขนาดประชากร ความแตกต่างนี้จะถือว่าน้อยจนละเลยได้

วัตถุประสงค์การเรียนรู้ UNC-3.L: กำหนดว่าการแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่างสามารถอธิบายได้ว่าใกล้เคียงกับการแจกแจงปกติหรือไม่ [ทักษะ 3.C]

  • UNC-3.L.1 สำหรับตัวแปรเชิงหมวดหมู่, การแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่าง, $\hat{p}$, จะมีการแจกแจงที่ใกล้เคียงกับปกติ ได้หากขนาดตัวอย่างมีขนาดใหญ่เพียงพอ: $np \geq 10$ และ $n(1-p) \geq 10$

วัตถุประสงค์การเรียนรู้ UNC-3.M: ตีความความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่าง [ทักษะ 4.B]

  • UNC-3.M.1 ความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับสัดส่วนจากตัวอย่างควรตีความโดยใช้หน่วยที่เหมาะสมและอยู่ในบริบทของประชากรเฉพาะ

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

For a sample proportion $\hat{p}$ from an SRS: the mean is $p$ (unbiased), and the standard deviation is

$$\sigma_{\hat p}=\sqrt{\frac{p(1-p)}{n}}.$$
This spread has two names: it is the standard deviation of the sampling distribution, and it is called the standard error once you must estimate it from the sample (replacing $p$ by $\hat p$) — which is exactly what the later inference units do. It is approximately normal when $np\ge 10$ and $n(1-p)\ge 10$ (the Large Counts condition), and the $10\%$ condition ($n\le 0.10N$) keeps the observations near-independent.

Worked example. Suppose $40\%$ of voters favor a measure ($p=0.4$) and you sample $n=100$. The standard error is $\sigma_{\hat p}=\sqrt{\dfrac{0.4(0.6)}{100}}=0.049$. The chance a sample gives $\hat{p}>0.5$ is $z=\dfrac{0.5-0.4}{0.049}=2.04$, so $P(\hat p>0.5)\approx0.02$ – a majority in the sample would be surprising.

ไทย

สำหรับสัดส่วนตัวอย่าง $\hat{p}$ จาก SRS: ค่าเฉลี่ยคือ $p$ (ไม่มีความเบี่ยงเบน), และความเบี่ยงเบนมาตรฐานคือ

$$\sigma_{\hat p}=\sqrt{\frac{p(1-p)}{n}}.$$
การกระจายนี้มีชื่อสองชื่อ: คือ ความเบี่ยงเบนมาตรฐาน ของการแจกแจงตัวอย่าง, และเรียกว่า ค่าความคลาดเคลื่อนมาตรฐาน เมื่อต้องประมาณค่าจากตัวอย่าง (แทนที่ $p$ ด้วย $\hat p$) — ซึ่งนี่เองสิ่งที่หน่วยการอนุมานในภายหลังทำ จะ approximately normal เมื่อ $np\ge 10$ และ $n(1-p)\ge 10$ (Large Counts condition), และ条件 $10\%$ ($n\le 0.10N$) keeps the observations nearly independent.

ตัวอย่างฝึกหัด. สมมติว่า $40\%$ ของผู้ลงคะแนนเห็นด้วยกับมาตรการ ($p=0.4$) และคุณสุ่มตัวอย่าง $n=100$. ค่าความคลาดเคลื่อนมาตรฐานคือ $\sigma_{\hat p}=\sqrt{\dfrac{0.4(0.6)}{100}}=0.049$. โอกาสที่ตัวอย่างจะได้ $\hat{p}>0.5$ คือ $z=\dfrac{0.5-0.4}{0.049}=2.04$, ดังนั้น $P(\hat p>0.5)\approx0.02$ – การมีเสียงข้างมากในตัวอย่างจะเป็นเรื่องน่าประหลาดใจ

5.6

Comparing Two Groups: Difference of Sample Proportions · ⁨เปรียบเทียบสองกลุ่ม: ความต่างของสัดส่วนตัวอย่าง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.N: Determine parameters of a sampling distribution for a difference in sample proportions. [Skill 3.B]

  • UNC-3.N.1 For a categorical variable, when randomly sampling with replacement from two independent populations with population proportions $p_1$ and $p_2$, the sampling distribution of the difference in sample proportions $\hat{p}_1 - \hat{p}_2$ has mean, $\mu_{\hat{p}_1 - \hat{p}_2} = p_1 - p_2$ and standard deviation, $\sigma_{\hat{p}_1 - \hat{p}_2} = \sqrt{\dfrac{p_1(1-p_1)}{n_1} + \dfrac{p_2(1-p_2)}{n_2}}$.
  • UNC-3.N.2 If sampling without replacement, the standard deviation of the difference in sample proportions is smaller than what is given by the formula above. If the sample sizes are less than 10% of the population sizes, the difference is negligible.

Learning Objective UNC-3.O: Determine whether a sampling distribution for a difference of sample proportions can be described as approximately normal. [Skill 3.C]

  • UNC-3.O.1 The sampling distribution of the difference in sample proportions $\hat{p}_1 - \hat{p}_2$ will have an approximate normal distribution provided the sample sizes are large enough: $n_1 p_1 \geq 10, n_1(1-p_1) \geq 10, n_2 p_2 \geq 10, n_2(1-p_2) \geq 10$.

Learning Objective UNC-3.P: Interpret probabilities and parameters for a sampling distribution for a difference in proportions. [Skill 4.B]

  • UNC-3.P.1 Parameters for a sampling distribution for a difference of proportions should be interpreted using appropriate units and within the context of a specific populations.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.N: กำหนดพารามิเตอร์ของการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วนจากตัวอย่าง [ทักษะ 3.B]

  • UNC-3.N.1 สำหรับตัวแปรเชิงหมวดหมู่, เมื่อสุ่มตัวอย่างพร้อมการแทนที่จากสองประชากรที่เป็นอิสระโดยมีสัดส่วนประชากร $p_1$ และ $p_2$, การแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วนจากตัวอย่าง $\hat{p}_1 - \hat{p}_2$ จะมีค่าเฉลี่ย, $\mu_{\hat{p}_1 - \hat{p}_2} = p_1 - p_2$ และส่วนเบี่ยงเบนมาตรฐาน, $\sigma_{\hat{p}_1 - \hat{p}_2} = \sqrt{\dfrac{p_1(1-p_1)}{n_1} + \dfrac{p_2(1-p_2)}{n_2}}$
  • UNC-3.N.2 หากเป็นการสุ่มตัวอย่างโดยไม่มีการแทนที่ ส่วนเบี่ยงเบนมาตรฐานของผลต่างของสัดส่วนจากตัวอย่างจะมีค่าน้อยกว่าค่าที่ได้จากสูตรข้างต้น หากขนาดตัวอย่างมีค่าน้อยกว่า 10% ของขนาดประชากร ความแตกต่างนี้จะถือว่าน้อยจนละเลยได้

วัตถุประสงค์การเรียนรู้ UNC-3.O: กำหนดว่าการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วนจากตัวอย่างสามารถอธิบายได้ว่าใกล้เคียงกับการแจกแจงปกติหรือไม่ [ทักษะ 3.C]

  • UNC-3.O.1 การแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วนจากตัวอย่าง $\hat{p}_1 - \hat{p}_2$ จะมีการแจกแจงที่ใกล้เคียงกับปกติ ได้หากขนาดตัวอย่างมีขนาดใหญ่เพียงพอ: $n_1 p_1 \geq 10, n_1(1-p_1) \geq 10, n_2 p_2 \geq 10, n_2(1-p_2) \geq 10$

วัตถุประสงค์การเรียนรู้ UNC-3.P: ตีความความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วน [ทักษะ 4.B]

  • UNC-3.P.1 พารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของสัดส่วนควรตีความโดยใช้หน่วยที่เหมาะสมและอยู่ในบริบทของประชากรเฉพาะ

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

For $\hat{p}_1-\hat{p}_2$ from two independent samples: the mean is $p_1-p_2$, and because the samples are independent the variances add:

$$\sigma_{\hat p_1-\hat p_2}=\sqrt{\frac{p_1(1-p_1)}{n_1}+\frac{p_2(1-p_2)}{n_2}}.$$
It is approximately normal when the Large Counts condition holds in both samples.

ไทย

สำหรับ $\hat{p}_1-\hat{p}_2$ จากสองตัวอย่างที่เป็นอิสระ: ค่าเฉลี่ยคือ $p_1-p_2$, และเนื่องจากตัวอย่างเป็นอิสระกัน ความแปรปรวนบวกกัน:

$$\sigma_{\hat p_1-\hat p_2}=\sqrt{\frac{p_1(1-p_1)}{n_1}+\frac{p_2(1-p_2)}{n_2}}.$$
จะประมาณเป็นปกติเมื่อเงื่อนไขจำนวนมากเป็นจริงใน ทั้งสอง ตัวอย่าง

5.7

The Sampling Distribution of a Sample Mean · ⁨การแจกแจงของค่าเฉลี่ยตัวอย่าง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.Q: Determine parameters for a sampling distribution for sample means. [Skill 3.B]

  • UNC-3.Q.1 For a numerical variable, when random sampling with replacement from a population with mean $\mu$ and standard deviation, $\sigma$, the sampling distribution of the sample mean has mean $\mu_{\bar{x}} = \mu$ and standard deviation $\sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}}$.
  • UNC-3.Q.2 If sampling without replacement, the standard deviation of the sample mean is smaller than what is given by the formula above. If the sample size is less than 10% of the population size, the difference is negligible.

Learning Objective UNC-3.R: Determine whether a sampling distribution of a sample mean can be described as approximately normal. [Skill 3.C]

  • UNC-3.R.1 For a numerical variable, if the population distribution can be modeled with a normal distribution, the sampling distribution of the sample mean, $\bar{x}$, can be modeled with a normal distribution.
  • UNC-3.R.2 For a numerical variable, if the population distribution cannot be modeled with a normal distribution, the sampling distribution of the sample mean, $\bar{x}$, can be modeled approximately by a normal distribution, provided the sample size is large enough, e.g., greater than or equal to 30.

Learning Objective UNC-3.S: Interpret probabilities and parameters for a sampling distribution for a sample mean. [Skill 4.B]

  • UNC-3.S.1 Probabilities and parameters for a sampling distribution for a sample mean should be interpreted using appropriate units and within the context of a specific population.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.Q: กำหนดพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่าง [ทักษะ 3.B]

  • UNC-3.Q.1 สำหรับตัวแปรเชิงจำนวน, เมื่อสุ่มตัวอย่างพร้อมการแทนที่จากประชากรที่มีค่าเฉลี่ย $\mu$ และส่วนเบี่ยงเบนมาตรฐาน, $\sigma$, การแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่างจะมีค่าเฉลี่ย $\mu_{\bar{x}} = \mu$ และส่วนเบี่ยงเบนมาตรฐาน $\sigma_{\bar{x}} = \dfrac{\sigma}{\sqrt{n}}$
  • UNC-3.Q.2 หากเป็นการสุ่มตัวอย่างโดยไม่มีการแทนที่ ส่วนเบี่ยงเบนมาตรฐานของค่าเฉลี่ยจากตัวอย่างจะมีค่าน้อยกว่าค่าที่ได้จากสูตรข้างต้น หากขนาดตัวอย่างมีค่าน้อยกว่า 10% ของขนาดประชากร ความแตกต่างนี้จะถือว่าน้อยจนละเลยได้

วัตถุประสงค์การเรียนรู้ UNC-3.R: กำหนดว่าการแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่างสามารถอธิบายได้ว่าใกล้เคียงกับการแจกแจงปกติหรือไม่ [ทักษะ 3.C]

  • UNC-3.R.1 สำหรับตัวแปรเชิงจำนวน, หากการแจกแจงของประชากรสามารถจำลองได้ด้วยการแจกแจงปกติ, การแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่าง, $\bar{x}$, สามารถจำลองได้ด้วยการแจกแจงปกติ
  • UNC-3.R.2 สำหรับตัวแปรเชิงจำนวน, หากการแจกแจงของประชากรไม่สามารถจำลองได้ด้วยการแจกแจงปกติ, การแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่าง, $\bar{x}$, สามารถจำลองได้อย่างใกล้เคียงด้วยการแจกแจงปกติ ได้หากขนาดตัวอย่างมีขนาดใหญ่เพียงพอ เช่น มากกว่าหรือเท่ากับ 30

วัตถุประสงค์การเรียนรู้ UNC-3.S: ตีความความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่าง [ทักษะ 4.B]

  • UNC-3.S.1 ความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของสถิติตัวอย่างสำหรับค่าเฉลี่ยจากตัวอย่างควรตีความโดยใช้หน่วยที่เหมาะสมและอยู่ในบริบทของประชากรเฉพาะ

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

For a sample mean $\bar{x}$ from an SRS: the mean is $\mu$ (unbiased), and the standard deviation is

$$\sigma_{\bar x}=\frac{\sigma}{\sqrt{n}}.$$
Its shape is normal if the population is normal, or approximately normal for large $n$ by the CLT. Note the spread shrinks like $\sqrt{n}$ – quadrupling the sample halves the standard error.

Worked example. A population has $\mu=70$ and $\sigma=12$. For samples of $n=36$, the sampling distribution of $\bar{x}$ is centered at $70$ with standard error $\dfrac{12}{\sqrt{36}}=2$. The chance a sample mean exceeds $73$ is $z=\dfrac{73-70}{2}=1.5$, so $P(\bar x>73)\approx0.067$.

ไทย

สำหรับค่าเฉลี่ยตัวอย่าง $\bar{x}$ จาก SRS: ค่าเฉลี่ยคือ $\mu$ (ไม่มีความเบี่ยงเบน), และความเบี่ยงเบนมาตรฐานคือ

$$\sigma_{\bar x}=\frac{\sigma}{\sqrt{n}}.$$
รูปร่างจะเป็นปกติหากประชากรเป็นปกติ, หรือประมาณเป็นปกติสำหรับ $n$ ที่ใหญ่พอตามทฤษฎีบท CLT. ระวังการกระจายจะหดตัวแบบ $\sqrt{n}$ – การเพิ่มขนาดตัวอย่างสี่เท่าจะทำให้ค่าความคลาดเคลื่อนมาตรฐานลดลงครึ่งหนึ่ง

ตัวอย่างวิธีทำ. Population มี $\mu=70$ และ $\sigma=12$. สำหรับ samples of size $n=36$, sampling distribution of $\bar{x}$ has center at $70$ with standard error $\dfrac{12}{\sqrt{36}}=2$. ความน่าจะเป็นที่ sample mean exceeds $73$ equals $z=\dfrac{73-70}{2}=1.5$, therefore $P(\bar x>73)\approx0.067$.

การแจกแจงของค่าเฉลี่ยจะแคบลงและเป็นปกติมากขึ้นเมื่อ n เพิ่มขึ้น
ประชากรทางซ้ายมีความเบี่ยงเบนอย่างมาก แต่ทุกการแจกแจงของ $\bar{x}$ จะอยู่ตรงกลางที่ $\mu$. $n$ ที่ใหญ่ขึ้นทำให้ค่าความคลาดเคลื่อนมาตรฐาน $\sigma/\sqrt{n}$ หดตัว ดังนั้นกราฟจึงสูงขึ้นและแคบลง – และยังเรียบขึ้น: ยังเบี่ยงเบนชัดเจนที่ $n=2$, เป็นปกติเกือบสมบูรณ์ (เส้นประ) ที่ $n=30$.
Vocabulary · ⁨คำศัพท์⁩ Train · ⁨ฝึกฝน⁩
English ไทย
standard error/ˈstændəd ˈerə/ ความคลาดเคลื่อนมาตรฐาน
5.8

Comparing Two Groups: Difference of Sample Means · ⁨เปรียบเทียบสองกลุ่ม: ความต่างของค่าเฉลี่ยตัวอย่าง⁩

Syllabus · ⁨หลักสูตร⁩
English

Enduring Understanding (UNC-3): Probabilistic reasoning allows us to anticipate patterns in data.

Learning Objective UNC-3.T: Determine parameters of a sampling distribution for a difference in sample means. [Skill 3.B]

  • UNC-3.T.1 For a numerical variable, when randomly sampling with replacement from two independent populations with population means $\mu_1$ and $\mu_2$ and population standard deviations $\sigma_1$ and $\sigma_2$, the sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ has mean $\mu_{(\bar{x}_1 - \bar{x}_2)} = \mu_1 - \mu_2$ and standard deviation, $\sigma_{(\bar{x}_1 - \bar{x}_2)} = \sqrt{\dfrac{\sigma_1^2}{n_1} + \dfrac{\sigma_2^2}{n_2}}$.
  • UNC-3.T.2 If sampling without replacement, the standard deviation of the difference in sample means is smaller than what is given by the formula above. If the sample sizes are less than 10% of the population sizes, the difference is negligible.

Learning Objective UNC-3.U: Determine whether a sampling distribution of a difference in sample means can be described as approximately normal. [Skill 3.C]

  • UNC-3.U.1 The sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ can be modeled with a normal distribution if the two population distributions can be modeled with a normal distribution.
  • UNC-3.U.2 The sampling distribution of the difference in sample means $\bar{x}_1 - \bar{x}_2$ can be modeled approximately by a normal distribution if the two population distributions cannot be modeled with a normal distribution but both sample sizes are greater than or equal to 30.

Learning Objective UNC-3.V: Interpret probabilities and parameters for a sampling distribution for a difference in sample means. [Skill 4.B]

  • UNC-3.V.1 Probabilities and parameters for a sampling distribution for a difference of sample means should be interpreted using appropriate units and within the context of a specific populations.
ไทย

Enduring Understanding (UNC-3): การคิดแบบความน่าจะเป็นช่วยให้เราคาดการณ์ลวดลายในข้อมูล

วัตถุประสงค์การเรียนรู้ UNC-3.T: กำหนดพารามิเตอร์ของการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของค่าเฉลี่ยจากตัวอย่าง [ทักษะ 3.B]

  • UNC-3.T.1 สำหรับตัวแปรเชิงตัวเลข เมื่อสุ่มตัวอย่างแบบมีคืนจากสองประชากรที่เป็นอิสระกัน โดยมีค่าเฉลี่ยประชากร $\mu_1$ และ $\mu_2$ และส่วนเบี่ยงเบนมาตรฐานประชากร $\sigma_1$ และ $\sigma_2$ การกระจายของตัวอย่างของความแตกต่างในค่าเฉลี่ยตัวอย่าง $\bar{x}_1 - \bar{x}_2$ จะมีค่าเฉลี่ย $\mu_{(\bar{x}_1 - \bar{x}_2)} = \mu_1 - \mu_2$ และส่วนเบี่ยงเบนมาตรฐาน $\sigma_{(\bar{x}_1 - \bar{x}_2)} = \sqrt{\dfrac{\sigma_1^2}{n_1} + \dfrac{\sigma_2^2}{n_2}}$
  • UNC-3.T.2 หากเป็นการสุ่มตัวอย่างโดยไม่มีการแทนที่ ส่วนเบี่ยงเบนมาตรฐานของผลต่างของค่าเฉลี่ยจากตัวอย่างจะมีค่าน้อยกว่าค่าที่ได้จากสูตรข้างต้น หากขนาดตัวอย่างมีค่าน้อยกว่า 10% ของขนาดประชากร ความแตกต่างนี้จะถือว่าน้อยจนละเลยได้

วัตถุประสงค์การเรียนรู้ UNC-3.U: กำหนดว่าการแจกแจงของสถิติตัวอย่างสำหรับผลต่างของค่าเฉลี่ยจากตัวอย่างสามารถอธิบายได้ว่าใกล้เคียงกับการแจกแจงปกติหรือไม่ [ทักษะ 3.C]

  • UNC-3.U.1 การแจกแจงของตัวอย่างของความแตกต่างในค่าเฉลี่ย $\bar{x}_1 - \bar{x}_2$ สามารถจำลองด้วยการแจกแจงปกติได้ หากการแจกแจงของประชากรทั้งสองสามารถจำลองด้วยการแจกแจงปกติได้
  • UNC-3.U.2 การแจกแจงของตัวอย่างของความแตกต่างในค่าเฉลี่ย $\bar{x}_1 - \bar{x}_2$ สามารถจำลองโดยประมาณด้วยการแจกแจงปกติได้ หากการแจกแจงของประชากรทั้งสองไม่สามารถจำลองด้วยการแจกแจงปกติได้ แต่ขนาดตัวอย่างทั้งสองมีมากกว่าหรือเท่ากับ 30

วัตถุประสงค์การเรียนรู้ UNC-3.V: ตีความความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของตัวอย่างของความแตกต่างในค่าเฉลี่ย [ทักษะ 4.B]

  • UNC-3.V.1 ความน่าจะเป็นและพารามิเตอร์สำหรับการแจกแจงของตัวอย่างของความแตกต่างในค่าเฉลี่ยควรตีความโดยใช้หน่วยที่เหมาะสมและอยู่ในบริบทของประชากรเฉพาะ

Source: College Board AP Course and Exam Description · ⁨แหล่งที่มา: คำอธิบายหลักสูตรและข้อสอบ College Board AP⁩

English

For $\bar{x}_1-\bar{x}_2$ from two independent samples: the mean is $\mu_1-\mu_2$, and (independent, so variances add)

$$\sigma_{\bar x_1-\bar x_2}=\sqrt{\frac{\sigma_1^2}{n_1}+\frac{\sigma_2^2}{n_2}}.$$
This is the foundation for two-sample inference in the next units.

ไทย

สำหรับ $\bar{x}_1-\bar{x}_2$ จากสองตัวอย่างที่เป็นอิสระ: ค่าเฉลี่ยคือ $\mu_1-\mu_2$, และ (เป็นอิสระ ดังนั้นความแปรปรวนบวกกัน)

$$\sigma_{\bar x_1-\bar x_2}=\sqrt{\frac{\sigma_1^2}{n_1}+\frac{\sigma_2^2}{n_2}}.$$
นี่คือรากฐานสำหรับการอนุมานสองตัวอย่างในหน่วยถัดไป

5.8

Exam tips · ⁨ข้อแนะนำสำหรับการสอบ⁩

English
  • A sampling distribution is the distribution of a statistic over many samples, centered on the true parameter.
  • The Central Limit Theorem: for a large enough sample the sample mean is approximately normal, even if the population is not.
  • Larger samples give less variability (a smaller standard error).
  • Check the conditions (random, independent/10%, large enough) before using a normal model.
  • Keep straight what varies — the statistic — versus the fixed parameter.
ไทย
  • การแจกแจงตัวอย่าง คือการแจกแจงของสถิติหลายตัวอย่าง, อยู่ตรงกลางที่พารามิเตอร์จริง
  • ทฤษฎีบทขีดจำกัดกลาง: สำหรับตัวอย่างที่ใหญ่พอ ค่าเฉลี่ยตัวอย่างจะประมาณเป็นปกติ แม้ประชากรจะไม่เป็นปกติก็ตาม
  • ตัวอย่างที่ใหญ่กว่าให้ ความแปรปรวนน้อยลง (ค่าความคลาดเคลื่อนมาตรฐานเล็กลง)
  • ตรวจสอบเงื่อนไข (สุ่ม, อิสระ/10%, ใหญ่พอ) ก่อนใช้โมเดลปกติ
  • แยกให้ออกว่าอะไรเปลี่ยนแปลงได้ – สถิติ – เทียบกับพารามิเตอร์คงที่

Interactive lessons on this topic · ⁨บทเรียนเชิงโต้ตอบสำหรับหัวข้อนี้⁩

Work through it step by step, with instant-check exercises. · ⁨ทำทีละขั้นตอน พร้อมแบบฝึกหัดตรวจสอบผลทันที⁩

Past Papers · ⁨ข้อสอบย้อนหลัง⁩

More topics in AP Statistics · ⁨หัวข้อเพิ่มเติมใน AP Statistics⁩

Log in or create account · ⁨เข้าสู่ระบบหรือสร้างบัญชี⁩

IGCSE, A-Level & AP