קמברידג', שנות העשרים. במסיבת גינה, אישה אומרת דבר מפתיע. היא טוענת שהיא יכולה לטעום האם החלב נשפך לכוס…
English narration · English + 中文 subtitles burned in · קריאת קול באנגלית · תרגום אנגלי + סינית שרוף בתוך הסרטון
English
This handout covers Topic 6: Probability & Statistics 概率统计 2. It adds the Poisson model, combining random variables, continuous distributions, and the ideas of estimation and testing.
עברית
חומר זה מכסה נושא 6: הסתברות וסטטיסטיקה 2. הוא מוסיף את מודל פואסון, שילוב משתנים מקריים, התפלגויות רציפות, וגם רעיונות הערכה ובדיקה.
6.1
The Poisson distribution · ההתפלגות פואסון
Syllabus · סיילבוס
English
Candidates should be able to:
Notes and examples
• use formulae to calculate probabilities for the distribution $\text{Po}(\lambda)$
• use the fact that if $X \sim \text{Po}(\lambda)$ then the mean and variance of $X$ are each equal to $\lambda$
Proofs are not required.
• understand the relevance of the Poisson distribution to the distribution of random events, and use the Poisson distribution as a model
• use the Poisson distribution as an approximation to the binomial distribution where appropriate
The conditions that $n$ is large and $p$ is small should be known; $n > 50$ and $np < 5$, approximately.
• use the normal distribution, with continuity correction, as an approximation to the Poisson distribution where appropriate.
The condition that $\lambda$ is large should be known; $\lambda > 15$, approximately.
עברית
המועמדים אמורים להיות מסוגלים:
הערות לדוגמאות
• השתמש בנוסחאות כדי לחשב הסתברויות עבור ההתפלגות $\text{Po}(\lambda)$
• השתמש בעובדה כי אם $X \sim \text{Po}(\lambda)$, אזי הממוצע והשונות של $X$ שווים כולם ל-$\lambda$
הוכחות אינן נדרשות.
• הבן את הרלוונטיות של ההתפלגות פואסון להתפלגות אירועים רנדומליים, והשתמש ב-התפלגות פואסון כמודל
• השתמש בהתפלגות פואסון כקירוב להתפלגות בינומית כאשר מתאים
יש לדעת שהתנאי $n$ גדול ו$p$ קטן; ידוע גם כי $n > 50$ ו$np < 5$ בקירוב.
• השתמש בהתפלגות נורמלית, עם תיקון רציפות, כקירוב להתפלגות פואסון כאשר מתאים.
יש לדעת שהתנאי $\lambda$ גדול; ידוע גם כי $\lambda > 15$ בקירוב.
Source: Cambridge International syllabus · מקור: הסיילבוס הבינלאומי של קמבריד'ג'
English
The Poisson distribution 泊松分布$X \sim \mathrm{Po}(\lambda)$ models the number of random events in a fixed interval, when events happen at a steady average rate $\lambda$:
$$P(X = r) = e^{-\lambda}\frac{\lambda^r}{r!}.$$
For a Poisson variable the mean and the variance are both equal to $\lambda$. The Poisson distribution is a good approximation 近似 to the binomial distribution when $n$ is large and $p$ is small. The normal distribution (with continuity correction) approximates the Poisson when $\lambda$ is large.
Worked example.$X \sim \mathrm{Po}(3)$. Find $P(X = 2)$.
החלוקת פואסון$X \sim \mathrm{Po}(\lambda)$ מודל את מספר האירועים האקראיים במרווח קבוע, כאשר האירועים מתרחשים בקצב ממוצע יציב $\lambda$:
$$P(X = r) = e^{-\lambda}\frac{\lambda^r}{r!}.$$
משתנה לפואסון יש ממוצע ושונות המשווים לשני $\lambda$. החלוקת פואסון היא קירוב טוב לחלוקה בינומית כאשר $n$ גדול ו$p$ קטן. החלוקה הנורמלית (עם תיקון רציפות) מקרבת את פואסון כאשר $\lambda$ גדול.
דוגמה מפורטת.$X \sim \mathrm{Po}(3)$. מצאו $P(X = 2)$.
החלוקת פואסון $\mathrm{Po}(3)$: למשתנה לפואסון הממוצע והשונות שווים לשני $\lambda$.
Explore · חקור
The Poisson distribution · החלוקה הפואסונית
Change the mean λ. Poisson models the number of random events in a fixed interval — rare events give a skewed shape. · שנה את הממוצע λ. Poisson דומה למספר אירועים אקראיים ברווח זמן קבוע – אירועים נדירים נותנים צורה מעוותת.
6.2
Linear combinations of random variables · צירופים ליניאריים של משתנים אקראיים
Syllabus · סיילבוס
English
Candidates should be able to:
Notes and examples
• use, when solving problems, the results that – $\text{E}(aX + b) = a\text{E}(X) + b$ and $\text{Var}(aX + b) = a^2\text{Var}(X)$ – $\text{E}(aX + bY) = a\text{E}(X) + b\text{E}(Y)$ – $\text{Var}(aX + bY) = a^2\text{Var}(X) + b^2\text{Var}(Y)$ for independent $X$ and $Y$ – if $X$ has a normal distribution then so does $aX + b$ – if $X$ and $Y$ have independent normal distributions then $aX + bY$ has a normal distribution – if $X$ and $Y$ have independent Poisson distributions then $X + Y$ has a Poisson distribution.
Proofs of these results are not required.
עברית
המועמדים אמורים להיות מסוגלים:
הערות לדוגמאות
• השתמש, בפתרון בעיות, בתוצאות הבאות – $\text{E}(aX + b) = a\text{E}(X) + b$ ו$\text{Var}(aX + b) = a^2\text{Var}(X)$ – $\text{E}(aX + bY) = a\text{E}(X) + b\text{E}(Y)$ – $\text{Var}(aX + bY) = a^2\text{Var}(X) + b^2\text{Var}(Y)$ עבור $X$ ו$Y$ עצמאיים – אם $X$ בעל התפלגות נורמלית, אזי גם $aX + b$ – אם ל$X$ ול$Y$ יש התפלגויות נורמליות עצמאיות, אזי ל$aX + bY$ יש התפלגות נורמלית – אם ל$X$ ול$Y$ יש התפלגויות פואסון עצמאיות, אזי ל$X + Y$ יש התפלגות פואסון.
אינה דורשת הוכחות לתוצאות אלו.
Source: Cambridge International syllabus · מקור: הסיילבוס הבינלאומי של קמבריד'ג'
English
When you change a variable by a linear rule, the expectation 期望 (mean) and variance 方差 follow these rules:
$$E(aX + b) = aE(X) + b, \qquad \mathrm{Var}(aX + b) = a^2\,\mathrm{Var}(X).$$
Continuous random variables · משתנים אקראיים רציפים
Syllabus · סיילבוס
English
Candidates should be able to:
Notes and examples
• understand the concept of a continuous random variable, and recall and use properties of a probability density function
For density functions defined over a single interval only; the domain may be infinite, e.g. $\frac{3}{x^4}$ for $x \geqslant 1$.
• use a probability density function to solve problems involving probabilities, and to calculate the mean and variance of a distribution.
Including location of the median or other percentiles of a distribution by direct consideration of an area using the density function. Explicit knowledge of the cumulative distribution function is not included.
עברית
המועמדים אמורים להיות מסוגלים:
הערות לדוגמאות
• להבין את מושגמשתנה מקרי רציף, ולזכור ולהשתמש בתכונות שלפונקציית צפיפות הסתברות
עבור פונקציות צפיפות המוגדרות רק על תחום אחד; התחום עשוי להיות אינסופי, למשל $\frac{3}{x^4}$ עבור $x \geqslant 1$.
• להשתמש בפונקציית צפיפות הסתברות לפתרון בעיות הקשורות להסתברות, ולחשב אתהמוצע ואתהשונות של ההתפלגות.
כולל מיקוםהמדIAN או אחוזים אחרים של ההתפלגות על ידי בחישה ישירה של שטח באמצעות פונקציית הצפיפות. ידע ספציפי בפונקציית ההתפלגות המצטברת אינו נכלל.
Source: Cambridge International syllabus · מקור: הסיילבוס הבינלאומי של קמבריד'ג'
English
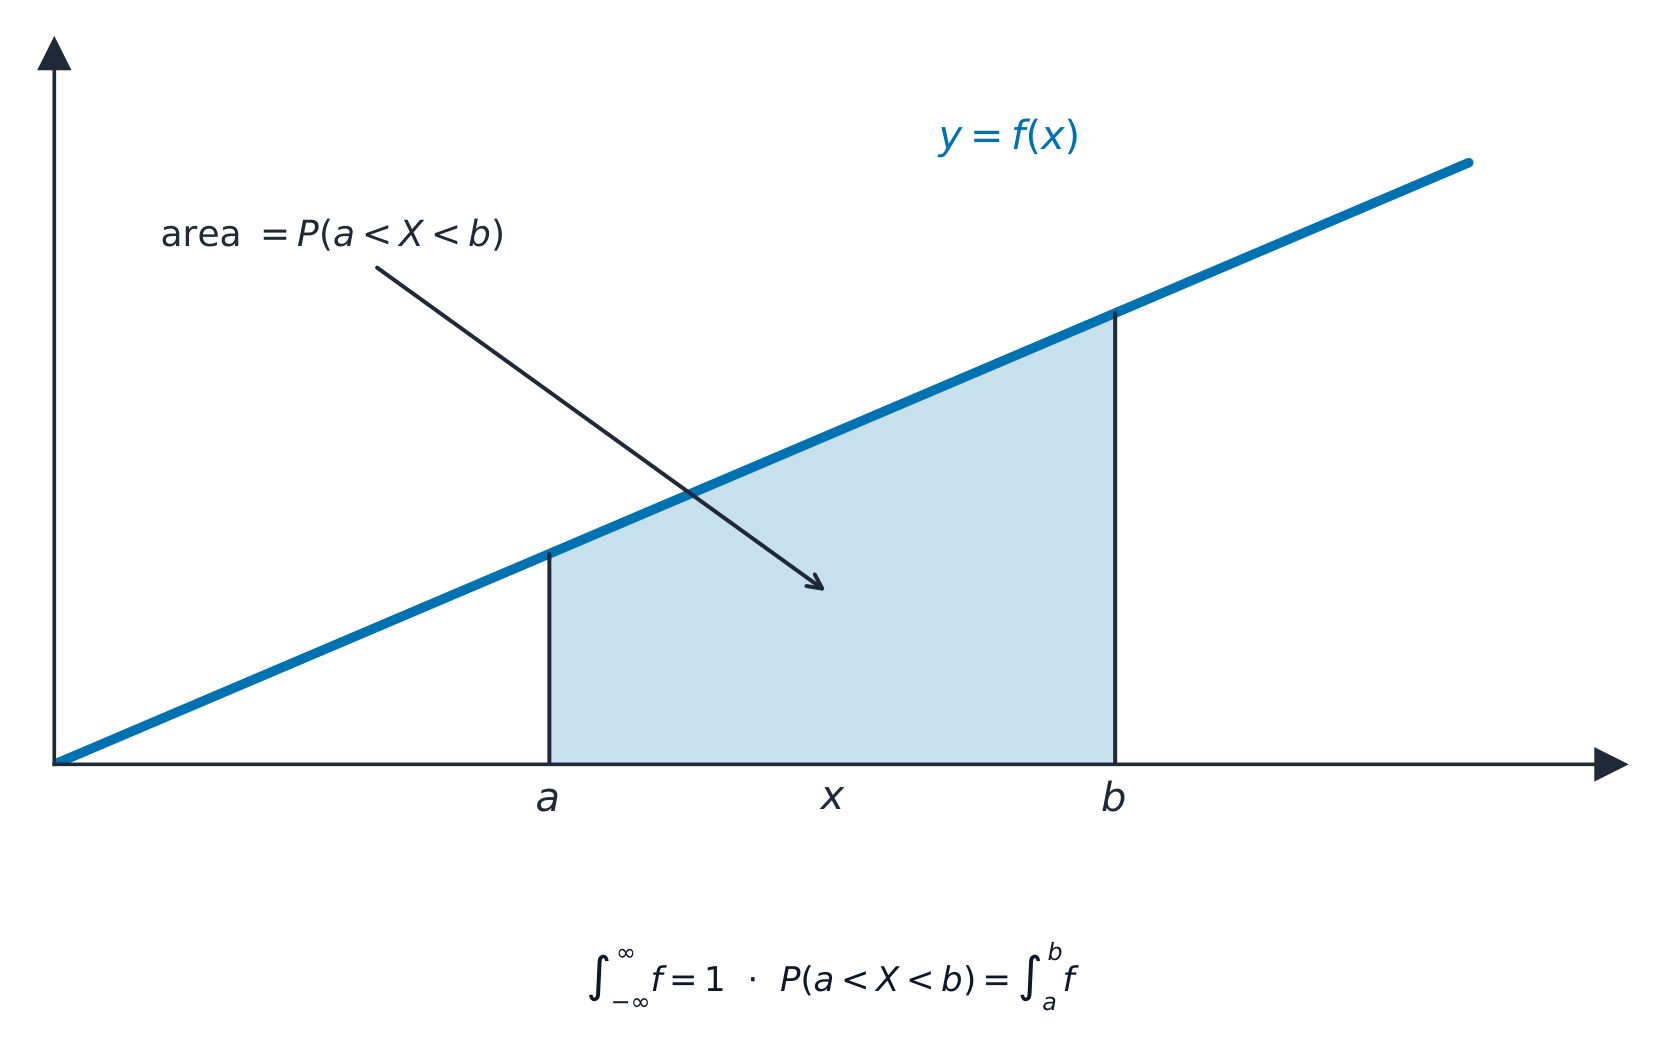
A continuous random variable 连续型随机变量 can take any value in a range. Its probabilities come from a probability density function 概率密度函数$f(x)$, with two key properties:
A probability is the area under $f$, and the mean is found by integration:
$$P(a < X < b) = \int_a^b f(x)\,dx, \qquad E(X) = \int_{-\infty}^{\infty} x\,f(x)\,dx.$$
The cumulative distribution function 累积分布函数 is $F(x) = P(X \leqslant x) = \int_{-\infty}^{x} f(t)\,dt$; the median 中位数 solves $F(m) = 0.5$, and other percentiles 百分位数 solve $F(x) = p$.
Worked example. A continuous variable has $f(x) = \tfrac12 x$ for $0 \leqslant x \leqslant 2$ (and $0$ elsewhere). Find $E(X)$.
The variance uses the same idea, $\mathrm{Var}(X)=\displaystyle\int_{-\infty}^{\infty}x^2 f(x)\,dx-\big(E(X)\big)^2$. For the same $f(x)=\tfrac12 x$ on $[0,2]$: $\displaystyle\int_0^2 x^2\cdot\tfrac12 x\,dx=\left[\tfrac{x^4}{8}\right]_0^2=2$, so $\mathrm{Var}(X)=2-\left(\tfrac43\right)^2=2-\tfrac{16}{9}=\tfrac{2}{9}$.
עברית
משתנה אקראי רציף יכול לקבל כל ערך בטווח נתון. ההסתברויות שלו נובעות מפונקציית צפיפות הסתברות$f(x)$, עם שתי תכונות מרכזיות:
השונות משתמשת באותה רעיון, $\mathrm{Var}(X)=\displaystyle\int_{-\infty}^{\infty}x^2 f(x)\,dx-\big(E(X)\big)^2$. עבור אותו $f(x)=\tfrac12 x$ ב$[0,2]$: $\displaystyle\int_0^2 x^2\cdot\tfrac12 x\,dx=\left[\tfrac{x^4}{8}\right]_0^2=2$, ולכן $\mathrm{Var}(X)=2-\left(\tfrac43\right)^2=2-\tfrac{16}{9}=\tfrac{2}{9}$.
Explore · חקור
Area = probability · שטח = הסתברות
P(a < X < b) = ∫ f(x) dx
For a continuous variable, probability is the area under the density curve between two values. · עבור משתנה רציף, הסתברות היא שטח מתחת לעקומת הצפיפות בין שני ערכים.
• understand the distinction between a sample and a population, and appreciate the necessity for randomness in choosing samples
• explain in simple terms why a given sampling method may be unsatisfactory
Including an elementary understanding of the use of random numbers in producing random samples. Knowledge of particular sampling methods, such as quota or stratified sampling, is not required.
• recognise that a sample mean can be regarded as a random variable, and use the facts that $\text{E}(\overline{X}) = \mu$ and that $\text{Var}(\overline{X}) = \frac{\sigma^2}{n}$
• use the fact that $\overline{X}$ has a normal distribution if $X$ has a normal distribution
• use the Central Limit Theorem where appropriate
Only an informal understanding of the Central Limit Theorem (CLT) is required; for large sample sizes, the distribution of a sample mean is approximately normal.
• calculate unbiased estimates of the population mean and variance from a sample, using either raw or summarised data
Only a simple understanding of the term 'unbiased' is required, e.g. that although individual estimates will vary the process gives an accurate result 'on average'.
• determine and interpret a confidence interval for a population mean in cases where the population is normally distributed with known variance or where a large sample is used
• determine, from a large sample, an approximate confidence interval for a population proportion.
עברית
המועמדים אמורים להיות מסוגלים:
הערות לדוגמאות
• להבין את ההבדל ביןדגימה לביןאוכלוסייה, ולהעריך את החשיבות שלאקראיות בבחירת הדגימות
• להסביר בפשטות מדוע שיטתדגימה נתונה עשויה להיות לא מספקת
כולל הבנה בסיסית לשימוש במספרים אקראיים בהפקתדגימות אקראיות. ידע בשיטות דגימה ספציפיות, כמו דגימת מכילה או דגימה שכבתית, אינו נדרש.
• להבין שממוצע הדגימה ניתן להתייחס אליו כמשתנה מקרי, ולהשתמש בעובדות כי $\text{E}(\overline{X}) = \mu$ וכי $\text{Var}(\overline{X}) = \frac{\sigma^2}{n}$
• להשתמש בעובדה כי $\overline{X}$ בעלהתפלגות נורמלית אם $X$ בעל התפלגות נורמלית
• להשתמש במשפט הגבול המרכזי כאשר מתאים
נדרשת רק הבנה לא-רשמית שלמשפט הגבול המרכזי (CLT); עבור גודל דגימה גדול, ההתפלגות של ממוצע הדגימה היא בקירוב נורמלית.
• לחשבאומדנים חסרי טעות שלמוצע האוכלוסייה ושלשונות האוכלוסייה מהדגימה, באמצעות נתונים ראשוניים או מסוכים
נדרשת רק הבנה פשוטה למונח 'חסר טעות', למשל: למרות שהאומדנים הבודדים עשויים להשתנות, התהליך נותן תוצאה מדויקת 'במידה ממוצעת'.
• לקבוע ולפרשמרווח סמך למוצע אוכלוסייה במקרים שבהם האוכלוסייה מחולקת נורמלית עם שונות ידועה או כאשר משתמשים בדגימה גדולה
• לקבוע, ממדגימה גדולה, מרווח סמך מקריב לפרופורציה באוכלוסייה.
Source: Cambridge International syllabus · מקור: הסיילבוס הבינלאומי של קמבריד'ג'
English
A sample 样本 is a small group chosen from the whole population 总体. A random sample needs randomness 随机性, so that every member has a fair chance of being chosen.
Some methods are unsatisfactory because they are biased 有偏: sampling only volunteers, or the first 20 people to arrive, over-represents certain kinds of people. A genuinely random sample uses random numbers – number every member of the population, then draw numbers (from a table or a generator) to decide who is in the sample.
The sample mean $\bar{X}$ is itself a random variable, with
By the Central Limit Theorem 中心极限定理, for a large sample $\bar{X}$ is approximately normal, whatever the shape of the population.
From a sample you can find unbiased estimates 无偏估计 of the population mean and variance. A confidence interval 置信区间 gives a range that probably contains the true mean. When the population is normal with known $\sigma$ (or the sample is large), a $95\%$ interval is
$$\bar{x} \pm 1.96\,\frac{\sigma}{\sqrt{n}}.$$
You can also find a confidence interval for a population proportion 总体比例 from a large sample.
Worked example. A sample of $n = 64$ has mean $\bar{x} = 50$, from a population with $\sigma = 8$. Find a $95\%$ confidence interval for the population mean.
דגימה היא קבוצה קטנה שנבחרה מה-אוכלוסייה כולה. דגימה אקראית דורשת אקראיות, כך שכל חבר יזכה להזדמנות שווה לבחירה.
חלק מהשיטות הן לא מספקות מכיוון שהן מוטות: דגימת מתנדבים בלבד, או 20 האנשים הראשונים שהגיעו, מייצגים יתר-מדי סוגים מסוימים של אנשים. דגימה אקראית אמיתית משתמשת ב-מספרים אקראיים – מספרים את כל חברי האוכלוסייה, ואז גוררים מספרים (מתוך טבלה או יצרן) כדי לקבוע מי נכלל בדגימה.
על פי המשפט המרכזי לגבי סכומים, עבור דגימה גדולה $\bar{X}$ הוא בקירוב נורמלי, ללא תלות בצורת האוכלוסייה.
ללא תלות בצורת האוכלוסייה, לתוחלת הדגימה $\bar{X}$ יש התפלגות צרה וקרובה לנורמלית הממוקדת סביב $\mu$.
מדגימה ניתן למצוא הערכות לא מוטות לתוחלת ולשונות האוכלוסייה. 区间 ביטחון נותן טווח שמסתבר שהוא מכיל את התוחלת האמיתית. כאשר האוכלוסייה נורמלית עם $\sigma$ ידוע (או הדגימה גדולה), $95\%$ interval is
$$\bar{x} \pm 1.96\,\frac{\sigma}{\sqrt{n}}.$$
מרווח סמך של $95\%$ משתרע $1.96$ טעויות סטנדרט משני צדי ממוצע הדוגמה.
ניתן גם למצוא מרווח סמך עבור פרופורציית אוכלוסיה מתוך דוגמה גדולה.
דוגמה מפורטת. לדוגמה בגודל $n = 64$ יש ממוצע $\bar{x} = 50$, מאוכלוסיה עם $\sigma = 8$. מצאו מרווח סמך של $95\%$ לממוצע האוכלוסיה.
By the Central Limit Theorem, sample means follow a normal curve — narrower for bigger samples. · על פי משפט הגבול המרכזי, ממוצעי דגימה נשחזרים לפי עקומה נורמלית — הצרה יותר לדגימות גדולות יותר.
• understand the nature of a hypothesis test, the difference between one-tailed and two-tailed tests, and the terms null hypothesis, alternative hypothesis, significance level, rejection region (or critical region), acceptance region and test statistic
Outcomes of hypothesis tests are expected to be interpreted in terms of the contexts in which questions are set.
• formulate hypotheses and carry out a hypothesis test in the context of a single observation from a population which has a binomial or Poisson distribution, using – direct evaluation of probabilities – a normal approximation to the binomial or the Poisson distribution, where appropriate
• formulate hypotheses and carry out a hypothesis test concerning the population mean in cases where the population is normally distributed with known variance or where a large sample is used
• understand the terms Type I error and Type II error in relation to hypothesis tests
• calculate the probabilities of making Type I and Type II errors in specific situations involving tests based on a normal distribution or direct evaluation of binomial or Poisson probabilities.
עברית
המועמדים אמורים להיות מסוגלים:
הערות לדוגמאות
• להבין את טבעו שלמבחן הנחה, ההבדל בין מבחניםחד-צדדיים ובין מבחניםדו-צדדיים, ואת המונחיםהנחת אפס, הנחת חלופית, רמת מובהקות, אזור דחייה (או אזור קריטי), אזור קבלה וסטטיסטי המבחן
מצופה שתוצאות מבחני ההנחה יפורשו בהקשר של נושא השאלה.
• לניסוח הנחות ולבצעמבחן הנחה בהקשר של תצפית אחת מאוכלוסייה בעלתהתפלגות בינומית אוהתפלגות פואסון, תוך שימוש ב– הערכה ישירה של הסתברות / קירוב נורמלי להתפלגות הבינומית או לפואסון, כאשר מתאים
• לניסוח הנחות ולבצעמבחן הנחה לגבי ממוצע האוכלוסייה במקרים שבהם האוכלוסייה מחולקת נורמלית עם שונות ידועה או כאשר משתמשים בדגימה גדולה
• להבין את המונחים שגיאת סוג I ושגיאת סוג II בהקשר של בדיקות הנחות
• לחשב את הסיכויים לבצע שגיאות סוג I ושגיאות סוג II במצבים ספציפיים הכוללים בדיקות המבוססות על חלוקה נורמלית או הערכה ישירה של סיכויים בינומיים או פואסון.
Source: Cambridge International syllabus · מקור: הסיילבוס הבינלאומי של קמבריד'ג'
English
A hypothesis test 假设检验 uses sample data to judge a claim. You set up two statements: the null hypothesis 原假设$H_0$ (the claim being tested, usually "no change") and the alternative hypothesis 备择假设$H_1$ (what you suspect instead). The test is one-tailed 单尾 if $H_1$ points one way (e.g. $\mu > 50$) and two-tailed 双尾 if it allows both ways ($\mu \neq 50$).
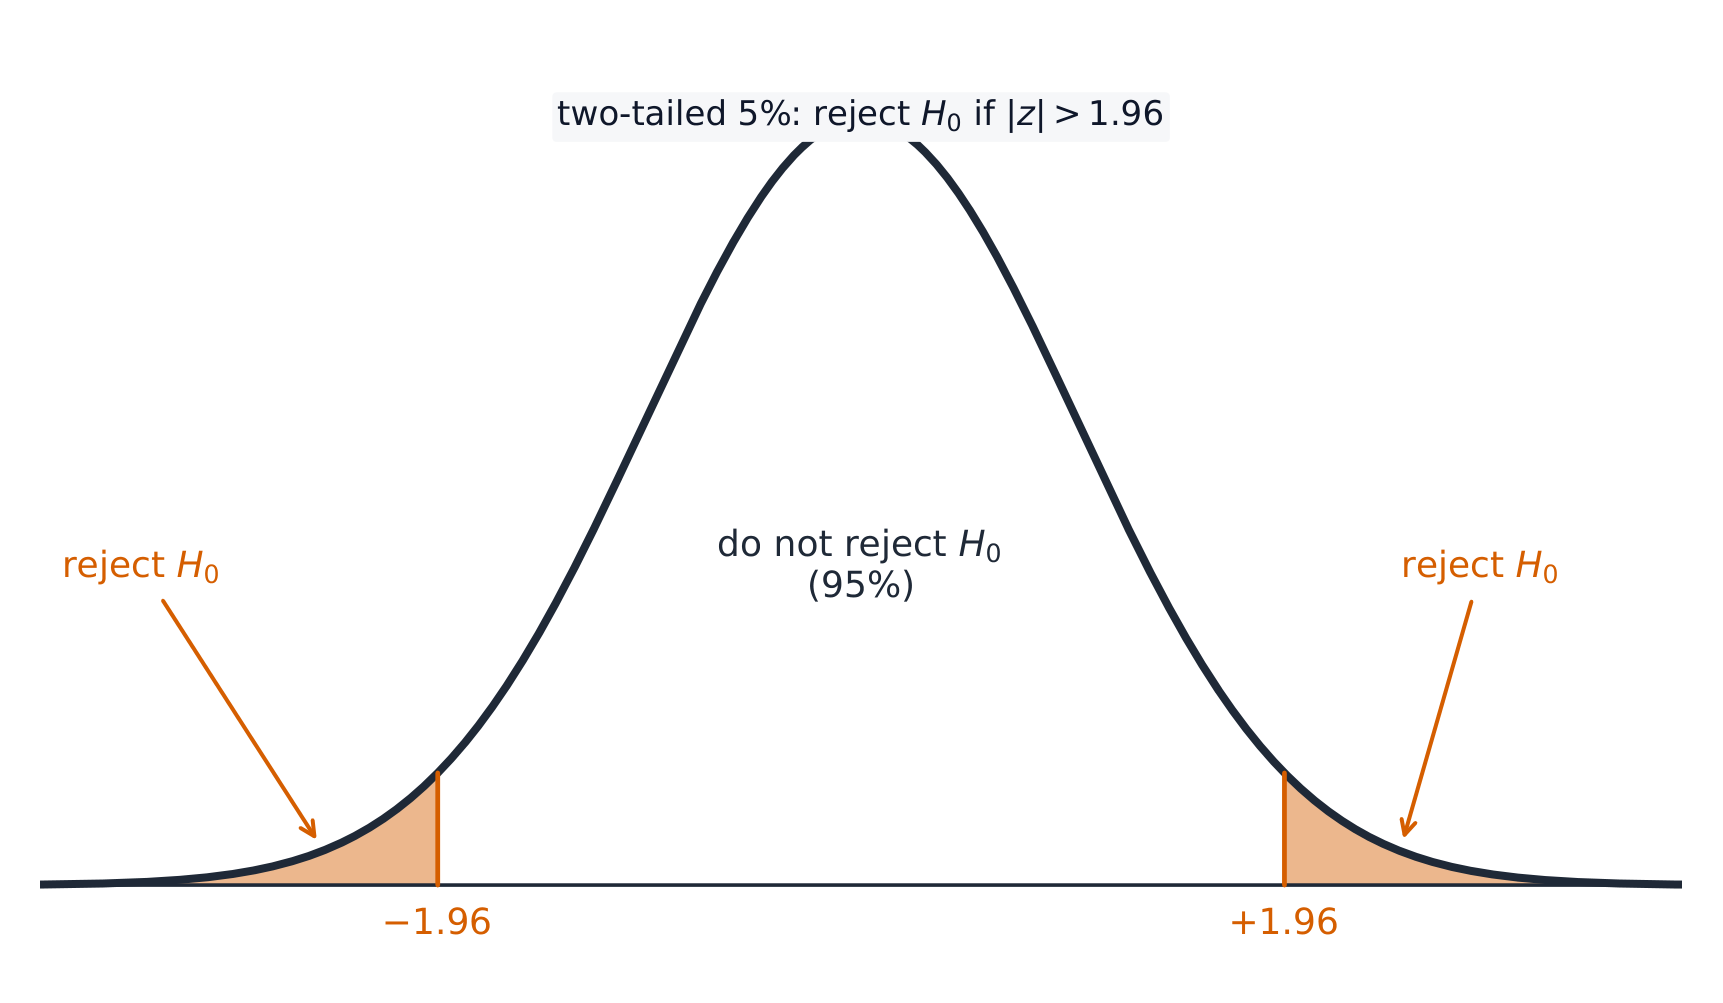
You fix a significance level 显著性水平 (often $5\%$), work out a test statistic 检验统计量 from the data, and see whether it lands in the rejection region 拒绝域 (also called the critical region); if it does you reject $H_0$, otherwise the statistic is in the acceptance region.
Two mistakes are possible: a Type I error 第一类错误 is rejecting $H_0$ when it is actually true; a Type II error 第二类错误 is accepting $H_0$ when it is actually false. You can find their probabilities from the rejection region: $P(\text{Type I})=P(\text{statistic in the rejection region}\mid H_0)$ – this equals the significance level – and $P(\text{Type II})=P(\text{statistic in the acceptance region}\mid H_1$ true for a stated value$)$, computed from the binomial, Poisson, or normal distribution.
Worked example. A population is claimed to have mean $50$, with $\sigma = 8$. A sample of $n = 64$ gives $\bar{x} = 52$. Test at the $5\%$ level whether the mean has changed.
$H_0\!: \mu = 50$ and $H_1\!: \mu \neq 50$ (two-tailed). The test statistic is
The critical value at $5\%$ (two-tailed) is $1.96$. Since $2 > 1.96$, you reject $H_0$: there is evidence the mean has changed.
Worked example (a binomial test). A coin is claimed fair but suspected of landing heads too rarely: $H_0\!:p=0.5$, $H_1\!:p<0.5$. In $n=30$ tosses you see $X=9$ heads. Under $H_0$, $X\sim B(30,0.5)$, so the one-tailed tail probability is
Since $0.021<0.05$, reject $H_0$: the coin does seem biased against heads. (For large $n$ the binomial is approximated by a normal; a Poisson test works the same way for rare events. And here, if the rule is "reject when $X\leqslant 9$", then $P(\text{Type I})=P(X\leqslant 9\mid p=0.5)\approx0.021$.)
עברית
מבחן הישג משתמש בנתוני דוגמה כדי להעריך טענה. אתם מגדירים שתי טענות: ההיפוטזה הריקה$H_0$ (הטענה הנבדקת, בדרך כלל "שינוי לא נעשה") וההיפוטזה האלטרנטיבית$H_1$ (מה שאתם סוברים במקום זאת). המבחן הוא חד-צדדי אם $H_1$ מצביע לכיוון אחד (למשל $\mu > 50$) ודו-צדדי אם הוא מאפשר שני כיוונים ($\mu \neq 50$).
אתם קובעים רמת מובהקות (לרוב $5\%$), מחשבים סטטיסטיקת מבחן מהנתונים, ובוחנים האם היא נופלת באזור הדחייה (נקרא גם אזור קריטי); אם כן, אתם דוחים את $H_0$, ואחרת הסטטיסטיקה נמצאת באזור הקבלה.
מבחן דו-צדדי ברמת $5\%$ דוחה את $H_0$ רק אם סטטיסטיקת המבחן נופלת בזנב המוצל מעבר ל$\pm1.96$.
שתי טעויות אפשריות: שגיאה מסוג I היא דחיית $H_0$ כשהיא אמיתית למעשה; שגיאה מסוג II היא קבלת $H_0$ כשהיא אמיתית למעשה. ניתן למצוא את ההסתברות שלהן מאזור הדחייה: $P(\text{Type I})=P(\text{statistic in the rejection region}\mid H_0)$ – שזה שווה לרמת המובהקות – ו$P(\text{Type II})=P(\text{statistic in the acceptance region}\mid H_1$ אמיתית לערך נתון$)$, שמחושבת מההתפלגות הבינומית, פואסון או נורמלית.
דוגמה מפורטת. טוענים שאוכלוסיה בעלת ממוצע $50$, עם $\sigma = 8$. דוגמה בגודל $n = 64$ נתנה ממוצע $\bar{x} = 52$. בדקו ברמת $5\%$ האם הממוצע השתנה.
$H_0\!: \mu = 50$ ו-$H_1\!: \mu \neq 50$ (דו-צדדי). ערך המבחן הוא
הערך הקריטי ב-$5\%$ (דו-צדדי) הוא $1.96$. מכיוון ש-$2 > 1.96$, דוחים את $H_0$: ישנן עדויות לכך שהממוצע השתנה.
דוגמה פותרת (מבחן בינומי). נטול טענה שהוא הוגן אך חשוד כי הוא נוטה לצלול ראשים נדירות מדי: $H_0\!:p=0.5$, $H_1\!:p<0.5$. ב-$n=30$ זריקות ראינו $X=9$ ראשים. תחת $H_0$, $X\sim B(30,0.5)$, ולכן הסתברות הזנב חד-צדדית היא
מכיוון ש-$0.021<0.05$, דוחים את $H_0$: הנטל אכן נראה כנטול איזון כלפי ראשים. (עבור $n$ גדולים, הבינומי מקורב על ידי התפלגות נורמלית; מבחן פואסון עובד באותו אופן לאירועים נדירים. וכאן, אם הכלל הוא "דוחים כאשר $X\leqslant 9$", אזי $P(\text{Type I})=P(X\leqslant 9\mid p=0.5)\approx0.021$).
Explore · חקור
The rejection region · אזור הדחייה
reject H₀ if z < −z* · דוחים את H₀ אם z < −z*
The shaded tail is the rejection region — if the test statistic lands there, reject H₀. · הזנב המוצל הוא אזור הדחייה — אם המספר הסטטיסטי של הבדיקה נופל בתוכו, דוחים את H₀.
Pick one and the site follows you — notes, papers, videos and practice all open on it. · בחרו נושא אחד והאתר יעקוב אחריו — הערות, מסמכים, וידאו ותרגולים פתוחים בו.
Type to search notes, lessons, code, vocabulary and past-paper questions across every subject. · הקלד כדי לחפש הערות, שיעורים, קוד, אוצר מילים ושאלות מבחנים בכל הנושאים.