Sampling and estimation · Échantillonnage et estimation
| English | Français |
|---|---|
| sample/ˈsæmpl/ | échantillon |
| population/ˌpɒpjʊˈleɪʃn/ | population |
| stratified/ˈstrætɪfaɪd/ | stratifié |
| systematic/ˌsɪstəˈmætɪk/ | systématique |
| cluster/ˈklʌstə/ | en grappe |
| sampling distribution/ˈsæmplɪŋ ˌdɪstrɪˈbjuːʃn/ | distribution d'échantillonnage |
| standard error/ˈstændəd ˈerə/ | erreur standard |
| Central Limit Theorem/ˈsentrəl ˈlɪmɪt ˈθɪərəm/ | Théorème Central Limite |
| confidence interval/ˈkɒnfɪdəns ˈɪntəvl/ | intervalle de confiance |
The poll that predicted the election
- A survey of 1000 people can predict the voting behaviour of 60 million. How?
- Sampling 样本 lets you draw conclusions about a whole population 总体 from a small, carefully chosen subset. The mathematics behind it is the foundation of all statistical inference.
Le sondage qui a prédit l'élection
- Un sondage de 1000 personnes peut prédire le comportement électoral de 60 millions. Comment ?
- L'échantillonnage 样本 permet de tirer des conclusions sur une population entière 总体 à partir d'un petit sous-ensemble soigneusement choisi. Les mathématiques derrière c'est le fondement de toute inférence statistique.
Populations and samples
- A population is the entire group you want to study. A sample is a small group from the population.
- Good sampling needs randomness — every member must have a known chance of being selected.
- Sampling methods: simple random, stratified 分层 (proportional from each subgroup), systematic 系统 (every $k$th member), cluster 整群.
Stratified sampling. A school has 600 boys and 400 girls. A stratified sample of 50: $\dfrac{600}{1000} \times 50 = 30$ boys and $\dfrac{400}{1000} \times 50 = 20$ girls.
The sample mean is nearly normal whatever the population shape
Populations et échantillons
- Une population est le groupe entier que vous souhaitez étudier. Un échantillon est un petit groupe tiré de la population.
- Un bon échantillonnage nécessite de la randomité — chaque membre doit avoir une chance connue d'être sélectionné.
- Méthodes d'échantillonnage : aléatoire simple, stratifié 分层 (proportionnel depuis chaque sous-groupe), systématique 系统 (tous les $k$es membres), par grappes 整群.
Échantillonnage stratifié. Une école compte 600 garçons et 400 filles. Un échantillon stratifié de 50 : $\dfrac{600}{1000} \times 50 = 30$ garçons et $\dfrac{400}{1000} \times 50 = 20$ filles.

La moyenne de l'échantillon est presque normale quelle que soit la forme de la population
The sampling distribution · La distribution d'échantillonnage
X̄ ~ N(μ, σ²/n)
By the Central Limit Theorem, sample means follow a normal · normale curve — narrower for bigger samples. · Par le Théorème Central Limite, les moyennes d'échantillon suivent une courbe normale — plus étroite pour des échantillons plus grands.
A school has 600 boys and 400 girls. A stratified sample of 50 needs how many boys? · Une école compte 600 garçons et 400 filles. Un échantillon stratifié de 50 nécessite combien de garçons ?
(600/1000) × 50 = 30 boys. · (600/1000) × 50 = 30 garçons.
The sampling distribution 抽样分布 of the mean
- The sample mean $\bar{X}$ is itself a random variable:
- The standard error 标准误 of the mean is $\dfrac{\sigma}{\sqrt{n}}$ — it shrinks as $n$ grows.
Statistics studies a sample to learn about a whole population
La distribution d'échantillonnage 抽样分布 de la moyenne
- La moyenne de l'échantillon $\bar{X}$ est elle-même une variable aléatoire :
- L'erreur standard 标准误 de la moyenne est $\dfrac{\sigma}{\sqrt{n}}$ — elle diminue lorsque $n$ augmente.
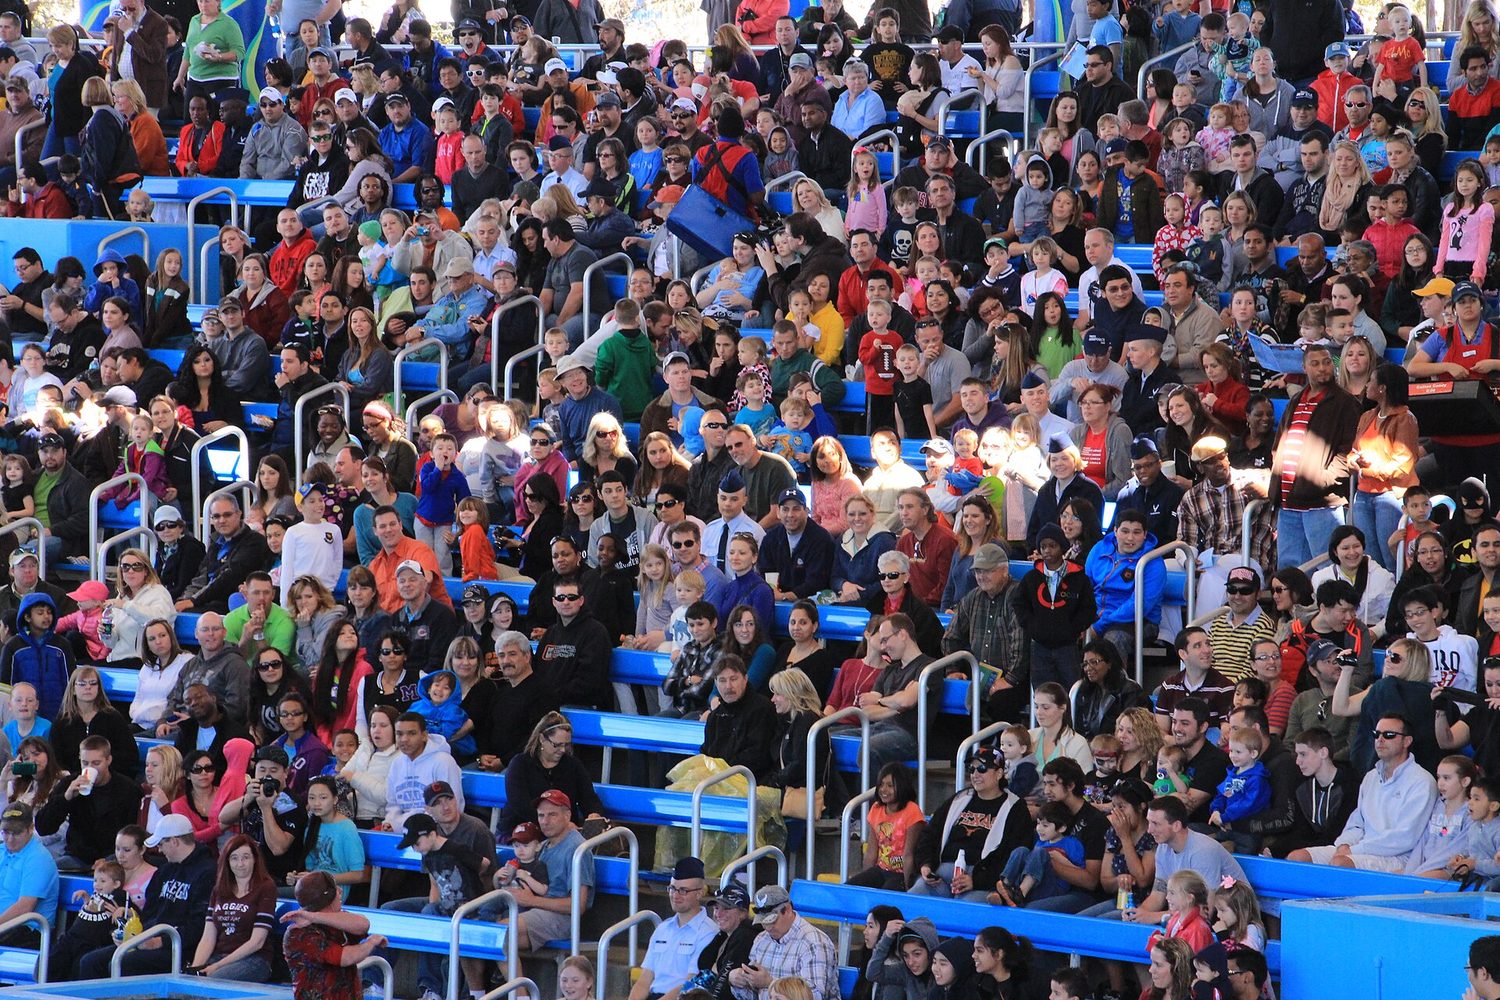
La statistique étudie un échantillon pour apprendre sur une population entière
A population has σ = 8. For a sample of n = 64, what is Var(X̄) = σ²/n? · Une population a σ = 8. Pour un échantillon de n = 64, quelle est Var(X̄) = σ²/n ?
Var(X̄) = σ²/n = 64/64 = 1.
A population has σ = 10 and n = 25. The standard error σ/√n = ? · Une population a σ = 10 et n = 25. L'erreur-type σ/√n = ?
σ/√n = 10/√25 = 10/5 = 2.
Match each sampling idea to its meaning. · Reliez chaque idée d'échantillonnage à sa signification.
The CLT makes sample means normal; their spread is σ²/n, giving the confidence interval. · Le TCL rend les moyennes d'échantillon normales ; leur dispersion est σ²/n, donnant l'intervalle de confiance.
The Central Limit Theorem 中心极限定理
- By the Central Limit Theorem, for a large sample ($n \geq 30$), $\bar{X}$ is approximately normal, whatever the population's shape.
- This is one of the most powerful results in all of mathematics — it lets us use the normal distribution even when the data isn't normal.
CLT applies to the mean, not the data. The Central Limit Theorem says the distribution of $\bar{X}$ becomes normal — not the individual data points. The raw data can have any shape.
A 95% confidence interval 置信区间 reaches 1.96 standard errors each side of the sample mean
Le théorème central limite 中心极限定理
- Par le théorème central limite, pour un grand échantillon ($n \geq 30$), $\bar{X}$ est approximativement normal, quelle que soit la forme de la population.
- C'est l'un des résultats les plus puissants en mathématiques — il nous permet d'utiliser la loi normale même lorsque les données ne sont pas normales.
Le TCL s'applique à la moyenne, pas aux données. Le théorème central limite dit que la distribution de $\bar{X}$ devient normale — pas les points de données individuels. Les données brutes peuvent avoir n'importe quelle forme.

Un intervalle de confiance à 95% s'étend sur 1.96 écarts-types de chaque côté de la moyenne de l'échantillon
By the Central Limit Theorem, the sample mean is approximately normal for a large sample, whatever the population shape. · Par le Théorème Central Limite, la moyenne d'échantillon est approximativement normale pour un grand échantillon, quel que soit la forme de la population.
The CLT makes X̄ approximately normal as the sample size grows. · Le TCL rend X̄ approximativement normal lorsque la taille de l'échantillon augmente.
The Central Limit Theorem says the individual data points become normally distributed for large samples. · Le Théorème Central Limite dit que les données individuelles deviennent normalement distribuées pour de grands échantillons.
The CLT applies to the sample mean X̄, not the individual data points. The raw data can have any shape. · Le TCL s'applique à la moyenne d'échantillon X̄, pas aux données individuelles. Les données brutes peuvent avoir n'importe quelle forme.
Confidence intervals
- A confidence interval gives a range that probably contains the true mean.
- For a normal population with known $\sigma$ (or a large sample), a 95% interval is:
- From a random sample find unbiased estimates of the mean and variance ('unbiased' = correct on average), and a confidence interval for a population proportion; random numbers help choose the sample.
Intervalles de confiance
- Un intervalle de confiance donne une plage qui contient probablement la vraie moyenne.
- Pour une population normale avec une variance connues $\sigma$ (ou un grand échantillon), un intervalle de 95 % est :
- À partir d'un échantillon aléatoire, trouvez des estimations sans biais de la moyenne et de la variance ('sans biais' = correct en moyenne), et un intervalle de confiance pour une proportion de population ; les nombres aléatoires aident à choisir l'échantillon.
A sample of n = 64 has σ = 8. What is the margin 1.96 × σ/√n for a 95% interval? (2 dp) · Un échantillon de taille n = 64 a σ = 8. Quelle est la marge 1.96 × σ/√n pour un intervalle de confiance à 95 % ? (2 décimales)
1.96 × 8/√64 = 1.96 × 8/8 = 1.96.
You've got it
- $E(\bar{X}) = \mu$, $\text{Var}(\bar{X}) = \dfrac{\sigma^2}{n}$; CLT makes $\bar X$ ≈ normal for large $n$
- a 95% confidence interval: $\bar{x} \pm 1.96\dfrac{\sigma}{\sqrt{n}}$
- good sampling needs randomness
Vous avez compris
- $E(\bar{X}) = \mu$, $\text{Var}(\bar{X}) = \dfrac{\sigma^2}{n}$ ; le TCL rend $\bar X$ ≈ normal pour grand $n$
- un intervalle de confiance à 95 % : $\bar{x} \pm 1.96\dfrac{\sigma}{\sqrt{n}}$
- un bon échantillonnage nécessite de la randomité