Sampling and estimation · 抽样与估计
| English | 中文 | Pinyin · 拼音 |
|---|---|---|
| sample/ˈsæmpl/ | 样本 | yàng běn |
| population/ˌpɒpjʊˈleɪʃn/ | 总体 | zǒng tǐ |
| stratified/ˈstrætɪfaɪd/ | 分层 | fēn céng |
| systematic/ˌsɪstəˈmætɪk/ | 系统 | xì tǒng |
| cluster/ˈklʌstə/ | 整群 | zhěng qún |
| sampling distribution/ˈsæmplɪŋ ˌdɪstrɪˈbjuːʃn/ | 抽样分布 | chōu yàng fēn bù |
| standard error/ˈstændəd ˈerə/ | 标准误 | biāo zhǔn wù |
| Central Limit Theorem/ˈsentrəl ˈlɪmɪt ˈθɪərəm/ | 中心极限定理 | zhōng xīn jí xiàn dìng lǐ |
| confidence interval/ˈkɒnfɪdəns ˈɪntəvl/ | 置信区间 | zhì xìn qū jiān |
The poll that predicted the election
- A survey of 1000 people can predict the voting behaviour of 60 million. How?
- Sampling 样本 lets you draw conclusions about a whole population 总体 from a small, carefully chosen subset. The mathematics behind it is the foundation of all statistical inference.
预测了选举的民调
- 一个 1000 人的调查能预测 6000 万人的投票行为。怎么做到的?
- 抽样(sampling)让你从一个小的、精心选择的子集得出关于整个总体的结论。它背后的数学是所有统计推断的基础。
Populations and samples
- A population is the entire group you want to study. A sample is a small group from the population.
- Good sampling needs randomness — every member must have a known chance of being selected.
- Sampling methods: simple random, stratified 分层 (proportional from each subgroup), systematic 系统 (every $k$th member), cluster 整群.
Stratified sampling. A school has 600 boys and 400 girls. A stratified sample of 50: $\dfrac{600}{1000} \times 50 = 30$ boys and $\dfrac{400}{1000} \times 50 = 20$ girls.
The sample mean is nearly normal whatever the population shape
总体与样本
- 一个总体(population)是你想研究的整个群体。一个样本(sample)是来自总体的一个小群体。
- 好的抽样需要随机性(randomness)——每个成员必须有一个已知的被选中的机会。
- 抽样方法:简单随机、分层(stratified,从每个子群体按比例)、系统(每第 $k$ 个成员)、整群。
分层抽样。 一所学校有 600 个男生和 400 个女生。一个 50 人的分层样本:$\dfrac{600}{1000} \times 50 = 30$ 个男生和 $\dfrac{400}{1000} \times 50 = 20$ 个女生。

无论总体形状如何,样本平均数都近乎正态
The sampling distribution · 抽样分布
X̄ ~ N(μ, σ²/n)
By the Central Limit Theorem, sample means follow a normal · 正态分布 curve — narrower for bigger samples. · 由中心极限定理,样本平均数遵循一条正态曲线——样本越大越窄。
A school has 600 boys and 400 girls. A stratified sample of 50 needs how many boys? · 一所学校有 600 个男生和 400 个女生。一个 50 人的分层样本需要多少个男生?
(600/1000) × 50 = 30 boys. · (600/1000) × 50 = 30 个男生。
The sampling distribution 抽样分布 of the mean
- The sample mean $\bar{X}$ is itself a random variable:
- The standard error 标准误 of the mean is $\dfrac{\sigma}{\sqrt{n}}$ — it shrinks as $n$ grows.
Statistics studies a sample to learn about a whole population
平均数的抽样分布
- 样本平均数 $\bar{X}$ 本身是一个随机变量:
- 平均数的标准误差(standard error)是 $\dfrac{\sigma}{\sqrt{n}}$——它随 $n$ 增长而缩小。
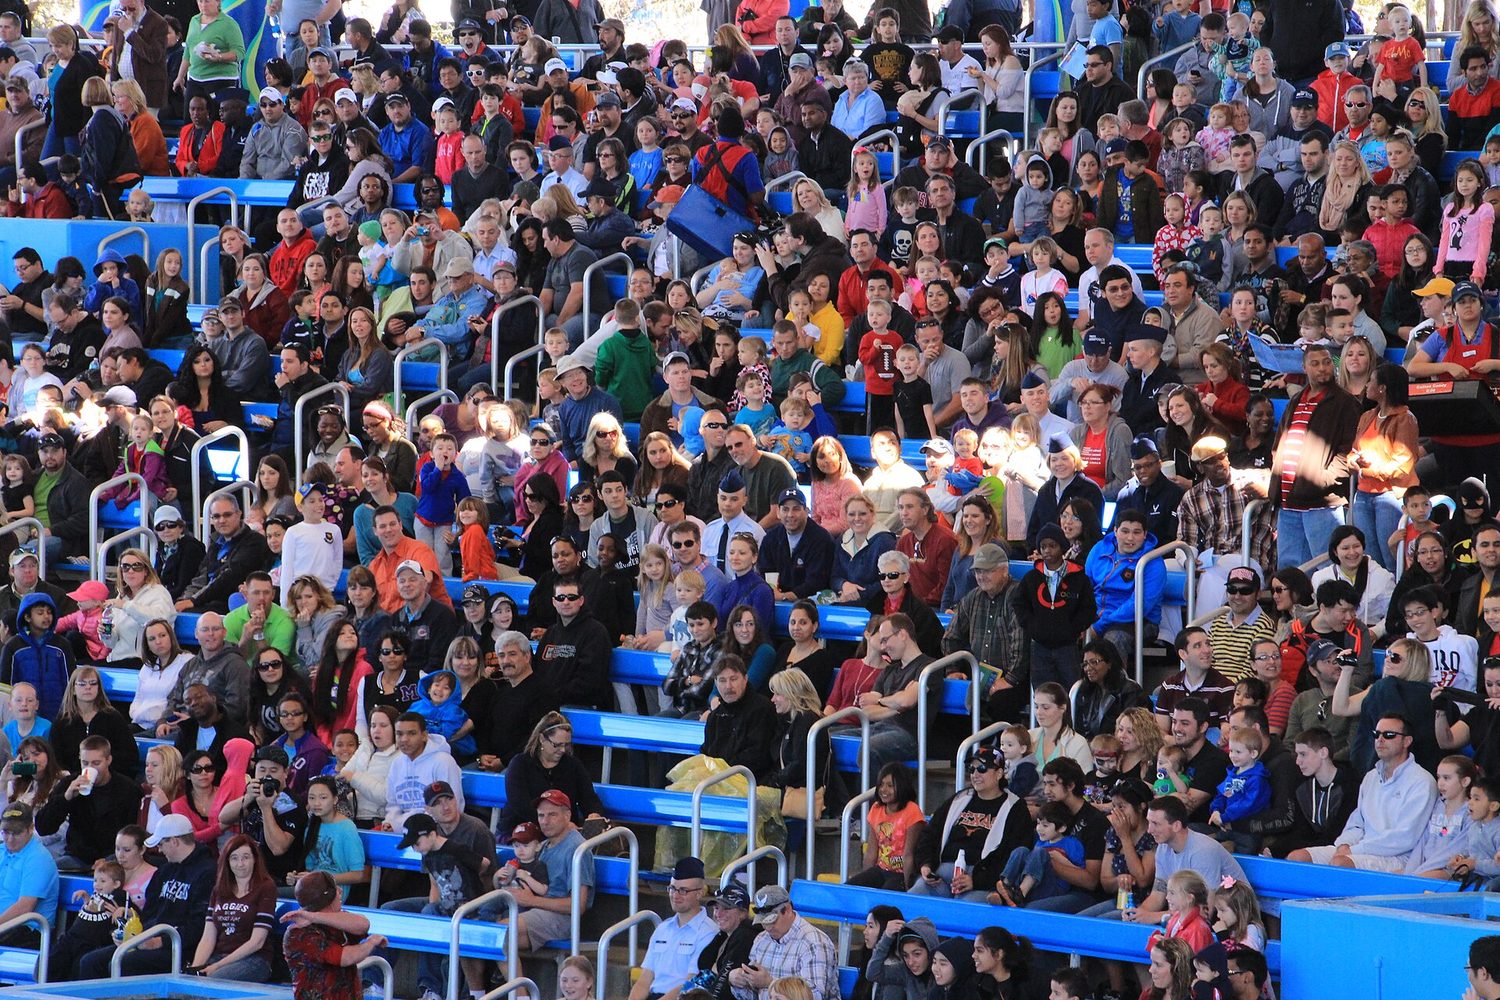
统计学研究一个样本来了解一个整个总体
A population has σ = 8. For a sample of n = 64, what is Var(X̄) = σ²/n? · 一个总体有 σ = 8。对一个 n = 64 的样本,Var(X̄) = σ²/n 是多少?
Var(X̄) = σ²/n = 64/64 = 1. · Var(X̄) = σ²/n = 64/64 = 1。
A population has σ = 10 and n = 25. The standard error σ/√n = ? · 一个总体有 σ = 10 而 n = 25。标准误差 σ/√n = ?
σ/√n = 10/√25 = 10/5 = 2. · σ/√n = 10/√25 = 10/5 = 2。
Match each sampling idea to its meaning. · 把每个抽样概念与它的含义配对。
The CLT makes sample means normal; their spread is σ²/n, giving the confidence interval. · 中心极限定理使样本平均数正态;它们的离散是 σ²/n,给出置信区间。
The Central Limit Theorem 中心极限定理
- By the Central Limit Theorem, for a large sample ($n \geq 30$), $\bar{X}$ is approximately normal, whatever the population's shape.
- This is one of the most powerful results in all of mathematics — it lets us use the normal distribution even when the data isn't normal.
CLT applies to the mean, not the data. The Central Limit Theorem says the distribution of $\bar{X}$ becomes normal — not the individual data points. The raw data can have any shape.
A 95% confidence interval 置信区间 reaches 1.96 standard errors each side of the sample mean
中心极限定理
- 由中心极限定理(Central Limit Theorem),对一个大样本($n \geq 30$),$\bar{X}$ 近似正态,无论总体的形状如何。
- 这是所有数学中最强大的结果之一——它让我们即使在数据不正态时也能用正态分布。
CLT 适用于平均数,不是数据。 中心极限定理说 $\bar{X}$ 的分布变正态——不是单个数据点。原始数据可以有任何形状。

一个 95% 置信区间从样本平均数向每边伸出 1.96 个标准误差
By the Central Limit Theorem, the sample mean is approximately normal for a large sample, whatever the population shape. · 由中心极限定理,对一个大样本,样本平均数近似正态,无论总体形状如何。
The CLT makes X̄ approximately normal as the sample size grows. · CLT 使 X̄ 随样本量增长而近似正态。
The Central Limit Theorem says the individual data points become normally distributed for large samples. · 中心极限定理说对大样本单个数据点变成正态分布。
The CLT applies to the sample mean X̄, not the individual data points. The raw data can have any shape. · CLT 适用于样本平均数 X̄,不是单个数据点。原始数据可以有任何形状。
Confidence intervals
- A confidence interval gives a range that probably contains the true mean.
- For a normal population with known $\sigma$ (or a large sample), a 95% interval is:
- From a random sample find unbiased estimates of the mean and variance ('unbiased' = correct on average), and a confidence interval for a population proportion; random numbers help choose the sample.
置信区间
- 一个置信区间(confidence interval)给出一个很可能包含真实平均数的范围。
- 对一个 $\sigma$ 已知的正态总体(或一个大样本),一个 95% 区间是:
- 从随机样本(random samples)求均值和方差(variance)的无偏估计(unbiased estimates,“无偏”即平均而言 on average 正确),以及总体比例(population proportion)的置信区间;随机数(random numbers)帮助选样。
A sample of n = 64 has σ = 8. What is the margin 1.96 × σ/√n for a 95% interval? (2 dp) · 一个 n = 64 的样本有 σ = 8。一个 95% 区间的边际 1.96 × σ/√n 是多少?(2 位小数)
1.96 × 8/√64 = 1.96 × 8/8 = 1.96. · 1.96 × 8/√64 = 1.96 × 8/8 = 1.96。
You've got it
- $E(\bar{X}) = \mu$, $\text{Var}(\bar{X}) = \dfrac{\sigma^2}{n}$; CLT makes $\bar X$ ≈ normal for large $n$
- a 95% confidence interval: $\bar{x} \pm 1.96\dfrac{\sigma}{\sqrt{n}}$
- good sampling needs randomness
你掌握了
- $E(\bar{X}) = \mu$,$\text{Var}(\bar{X}) = \dfrac{\sigma^2}{n}$;CLT 使 $\bar X$ 对大的 $n$ ≈ 正态
- 一个 95% 置信区间:$\bar{x} \pm 1.96\dfrac{\sigma}{\sqrt{n}}$
- 好的抽样需要随机性